# Getting Started
URL: https://usepioneer.ai/docs
## Pioneer researches leads so you don't have to
Pioneer is an AI research analyst for business development. You describe who you're looking for and what makes them a fit. Pioneer explores the open web, finds candidates, researches each one against your standards, and hands you a ranked board of leads, each with evidence you can check and the person you'd actually talk to.
That last part is what makes Pioneer different from a database. Databases filter what they already have. Pioneer *researches*. If the answer exists anywhere on the public web, whether a funding announcement, a job posting, a sustainability report, or a conference panel, Pioneer can find it, cite it, and put it on your board. Finding your next customer, partner, investor, or vendor usually isn't a filtering problem. It's a research problem, and research is what Pioneer automates.
## Pick your path
**See the whole flow, start to finish** → [From signup to your first 50 qualified leads](/docs/first-50-leads) walks one real pipeline from a blank account to a ranked, exportable list. If you read one page in this Help Center, read that one.
**Create a pipeline right now** → [Create Your First Pipeline](/docs/first-pipeline) is the short version: describe, set criteria, review your first batch.
**You'd rather let your agent run Pioneer** → [Use Pioneer With Your Agent](/docs/agents). Paste a one-line setup message into Claude, ChatGPT, or Codex, and the agent drives the product for you.
**There's already a pipeline in your account** → That's a gift, not a glitch. [We may have built it for you](/docs/first-pipeline#your-first-pipeline-might-already-exist).
**You already have a list** → [Import Your Own Leads](/docs/features/import). Paste names, links, or rows from a spreadsheet, and Pioneer researches and qualifies them exactly like leads it discovers.
**Your results aren't quite right** → [Refine Your Pipeline](/docs/guides/refining). Five minutes of refinement after each batch is the single most valuable habit in Pioneer.
**You need the person, not just the company** → [Find the Right People](/docs/guides/people). This finds the actual human in the role you care about, with verified contact details. Found, never guessed.
**You'd rather be introduced than write cold** → [My Network](/docs/features/my-network). Bring in the people you know, and Pioneer finds warm paths from your contacts to the people on your leads.
**Pioneer got something wrong** → [Correct Pioneer's Research](/docs/guides/accuracy). Flag it once and it never comes back.
**Someone outside Pioneer needs to see your board** → [Sharing a Pipeline](/docs/features/sharing). They get a read-only view from a link in their inbox, with no account and no login.
**Something looks stuck or broken** → [Troubleshooting & FAQ](/docs/troubleshooting).
## How Pioneer works, in one story
1. **Tell Pioneer what you're looking for.** A [pipeline](/docs/pipelines) starts with a plain-language description plus [criteria](/docs/concepts/criteria): MUST rules for deal-breakers, SHOULD rules for preferences. This is you teaching Pioneer your taste, the most important words you'll write in the product.
2. **Pioneer explores the web.** [Discovery](/docs/concepts/discovery) isn't a keyword search. Pioneer tries multiple search strategies, follows promising results deeper, and keeps exploring until it's confident it has covered the space, the way a diligent human researcher would, at scale.
3. **Every lead arrives already researched.** Each candidate is evaluated against every one of your criteria, with evidence and reasoning you can [read on the card](/docs/concepts/leads). A lead is **relevant** only when every MUST criterion passes. That's a rule, not a vibe.
4. **You review; Pioneer learns.** Approve, reject, and steer on [your board](/docs/pipelines). Every move is feedback, and [refinement](/docs/guides/refining) turns your reactions into a measurably better next batch.
5. **Research becomes outreach.** [Properties](/docs/features/properties) build each lead into a dossier, [Person properties](/docs/guides/people) resolve the human with a verified way to reach them, and [export](/docs/features/export) carries everything into your CRM or outreach tool.
Pioneer's end-to-end flow from purpose to export
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
Visit our [Legal & Trust Center](/legal) for terms of service, privacy policy, DPA, and security documentation.
# From Signup to Your First 50 Qualified Leads
URL: https://usepioneer.ai/docs/first-50-leads
This page walks the entire Pioneer journey once, end to end. By the time you finish it, you'll know how to go from a brand-new account to a board of qualified [leads](/docs/concepts/leads), with a named decision-maker and a verified email on the best ones, because you'll watch one founder do exactly that. Every other page in this Help Center goes deeper on one step of this journey. This page is the map.
## Meet Maya, who needs customers no database can list
Maya Torres is the founder of Calyx Thermal, a seed-stage climate-tech company. Calyx makes thermal batteries: insulated boxes of very hot bricks that let a factory replace its gas boiler with cheap off-peak electricity. The product works. Her problem is distribution. She needs five pilot customers this year, and the right pilot customer is weirdly specific. A mid-size food or beverage processor in the western US. Steam-heavy production. Aging gas boilers. Ideally, a public commitment to decarbonize.
No database sells that list. LinkedIn can filter by industry and headcount, but it can't read a bond filing and notice that a tomato processor in Fresno still runs two boilers from the 1990s. Finding Maya's customers isn't a filtering problem. It's a **research** problem, the kind that used to take a skilled human dozens of hours.
That research problem is exactly what Pioneer does. The rest of this page follows Maya from her first login to a CSV of qualified leads, and explains *why* each step works the way it does.
## Sign up, and check whether a pipeline is already waiting for you
Maya first heard about Pioneer through a short email that linked to something unusual: a live [pipeline](/docs/pipelines) Pioneer had already built about *Calyx's* problem, with real researched leads in it. When she signs up with her work email, that pipeline is transferred into her brand-new workspace automatically, already populated.
{/* SCREENSHOT: the /pipelines page immediately after signup, showing a pre-built pipeline card (e.g. "Food & beverage processors for thermal battery pilots") with a lead count, above the suggested recipes section */}
Why Pioneer does this: the hardest claim any research tool can make is "our research is actually good." A pipeline about your own problem, full of leads you recognize as plausible, makes the claim self-evident. So when Pioneer reaches out to founders, the product itself is the demo.
If there's no pipeline waiting for you, you lose nothing. Onboarding (next step) builds the same thing in a few minutes, and every step after that is identical.
## Tell Pioneer who you are and what you're trying to accomplish
Right after signup, Maya confirms her name and job title on the **connect** screen and accepts the terms. Then she reaches the **agent handoff** page, where Pioneer offers a one-line setup message she can paste into the AI agent she already uses (Claude, ChatGPT, or any other), and her agent can set up Pioneer (even create her first pipeline) for her. Maya chooses the by-hand path, so she continues: optional context about her company, then the important step, her **purpose**: what she's trying to accomplish. She writes: *"Find pilot customers for industrial thermal batteries. Food and beverage processors with big heat loads."*
{/* SCREENSHOT: the onboarding purpose step: a textarea with the user's purpose typed in and AI-generated purpose suggestions visible below it */}
While she types, Pioneer is already researching her professional background and her company from the public web. But her stated purpose is weighted far above anything Pioneer infers: a person's own words about what they want beat any guess. That purpose powers **recipes**, which are specific, ready-to-run pipeline suggestions on the `/pipelines` page (on the agent-first path, this same purpose question is asked on the pipelines page itself). The more specific your purpose, the sharper the recipes ("Series A battery-recycling startups in the EU," not "companies in energy").
Two buttons matter on each recipe: **Try this** pre-fills a pipeline you can still edit before creating, and **Not for me** dismisses it, which also teaches Pioneer, so the next batch of recipes gets closer. See [Creating Your First Pipeline](/docs/first-pipeline) for the full creation flow, including starting from scratch.
## Open your pipeline: it's a question Pioneer keeps answering
Maya opens her pre-built pipeline. The best way to understand what she's looking at: a pipeline is a research question she asks once, that Pioneer keeps answering. Hers is *"Find mid-size food and beverage processors in the western US with steam-heavy production and aging gas boilers, that have signaled intent to decarbonize."*
The pipeline is a board. On the left sits the **Preferences** column, the pipeline's control center, showing what it's looking for. To the right, leads flow through columns: **Leads** (researched leads waiting for review, best matches first), **Relevant** (the first custom stage, seeded for every pipeline), any custom stages you add, **Done**, and **Rejected**.
{/* SCREENSHOT: a full pipeline board: Preferences column on the left, Leads column with several ranked cards, a custom stage, Done, and Rejected */}
Before touching any leads, Maya reviews what the pipeline believes. That's the next step, and it's the most valuable five minutes in all of Pioneer.
## Teach Pioneer what a great lead looks like
In the Preferences column, Maya clicks the pencil to open the editor and reads the pipeline's description and [criteria](/docs/concepts/criteria), the rules that define a good fit. Criteria deliberately do double duty: they guide **discovery** (what Pioneer searches for) and they drive **qualification** (how every found lead is judged, with evidence). That's why teaching them pays twice.
Criteria aren't filters. Each one is a plain-language description of something Maya is looking for, and Pioneer judges every lead against it individually, researching that specific company and deciding *how strongly* it matches what the criterion is asking for. Direct, unambiguous evidence is a strong match; one indirect signal is a moderate one. That judgment is made per lead, from that lead's evidence, which is why two companies can both satisfy the same rule and still sit far apart on the board.
What the two tiers do is tell Pioneer which of those descriptions are non-negotiable:
- **MUST** criteria are deal-breakers, and the relevance gate. A lead that fails any MUST is not relevant. Mechanically, no exceptions.
- **SHOULD** criteria say what Maya values without requiring it. They lift a lead's position on the board, but never disqualify.
Maya edits hers down to:
- **MUST:** Food or beverage processor that operates its own production facilities
- **MUST:** Mid-size, roughly 100 to 2,000 employees
- **MUST:** Facilities in the western US
- **SHOULD:** Steam-heavy processes (cooking, sterilizing, evaporation)
- **SHOULD:** Evidence of aging natural-gas boilers or planned boiler replacement
- **SHOULD:** A public decarbonization commitment
{/* SCREENSHOT: the pipeline editor open from the Preferences column, showing the description field and the MUST / SHOULD criteria lists mid-edit */}
Why two tiers instead of one list? Collapse them and every preference becomes a veto, or every requirement becomes negotiable. The MUSTs are Maya's contract with Pioneer; the SHOULDs are her taste. Keeping them separate is what lets the relevance verdict be honest later. It's also why a vague description is expensive: Pioneer has nothing concrete to judge a lead against for "should be innovative," so it muddies every lead's position.
Notice what "aging gas boilers" is doing as a SHOULD. It's the kind of thing no database has a column for, and exactly the kind of thing web research can find. Write criteria around evidence that exists publicly. Three to five criteria is plenty to start; you'll refine them once you see results.
## Watch your first leads arrive, already researched
With preferences saved, Pioneer gets to work. [Discovery](/docs/concepts/discovery) is not a keyword search. Pioneer explores the web the way a diligent human researcher would: running multiple search strategies, following promising results deeper, adjusting based on what it finds, and continuing until it's confident it has covered the space.
While that runs, an **Incoming** box sits directly above the Leads column showing every lead mid-research with a live progress indicator. Each candidate is checked to be the right kind of thing (a company, not a listicle *about* companies), resolved to its own website rather than a directory page, deduplicated against the pipeline, and then researched: content read, a summary written, and every one of Maya's criteria evaluated against evidence found on the web.
{/* SCREENSHOT: the Incoming box above the Leads column during a discovery run: several leads with live progress indicators, one showing a warning icon with a Retry affordance */}
If research on a lead fails or stalls, Pioneer shows it (a warning icon and a **Retry** button) rather than letting the lead silently vanish. A lead that disappears without explanation would make you doubt every lead that remains, so failures stay visible and fixable.
Two things worth knowing while you watch:
- **What this costs:** each new lead Pioneer discovers (or you import) spends one credit. Everything after that (the deep research, criteria evaluation, properties, people) is free. You never pay to learn more about a lead you already have. See [Credits & Billing](/docs/credits).
- **You can close the tab.** Discovery runs in the background, and when it finishes, Pioneer emails you a summary with your leads attached as CSV files.
## Open a lead and read the evidence
An hour later, Maya's Leads column holds a ranked batch. Top of the column: **Copper Kettle Foods**, a tomato processor in Fresno. She clicks the card.
The detail view opens with a one-paragraph **summary**, the TL;DR for deciding whether this lead deserves attention. Its first words are the verdict in plain terms: Copper Kettle's summary opens **"Relevant because…"**, which means every MUST criterion passed. A **"Mostly relevant"** or **"Partially relevant"** opener means a deal-breaker failed. Below it, the **criteria results**: every criterion with a verdict (**Met**, **Not Met**, or **Inconclusive**) and the reasoning behind each one, written from what Pioneer actually found on this company rather than from a lookup. For Copper Kettle, all three MUSTs are met, and the "aging boilers" SHOULD cites a municipal bond filing that names two 1990s-era gas boilers at the Fresno plant. The decarbonization SHOULD cites the company's 2025 sustainability page and its 40% emissions-reduction target.
{/* SCREENSHOT: the lead detail view for a relevant lead: summary at the top, criteria results below with Met verdicts expanded to show reasoning and cited evidence */}
Here's the rule that makes the board trustworthy: **a lead is relevant when, and only when, it meets every MUST criterion.** The decision is mechanical. Pioneer's AI writes the summaries and gathers the evidence, but it never overrules your rules. You wrote the standard; the standard decides.
The ordering is a separate question from the verdict. A lead's position comes from adding up how strongly it matched each criterion, with a met MUST weighing substantially more than a SHOULD, enough that relevant leads always sit above ones that failed a deal-breaker, while within each group the strongest evidence rises first. Copper Kettle is top of the column not because it scraped past three MUSTs, but because it matched them convincingly and picked up two SHOULDs with hard evidence.
**Inconclusive** means Pioneer couldn't find enough public evidence either way: an honest "don't know" instead of a confident guess. On a SHOULD it doesn't move the ranking, but on a MUST it counts as not met, since a MUST passes only on affirmative evidence. If one criterion comes back inconclusive on many leads, it's probably not answerable from public information, or phrased so that no evidence could confirm it; [Refining Your Pipeline](/docs/guides/refining) covers how to rewrite it. For how Pioneer keeps evidence honest, see [Accuracy](/docs/guides/accuracy).
## Triage the board: every card you move teaches Pioneer
Now the judgment call that only Maya can make. She works down the Leads column: **Approve** the ones worth pursuing (they move to the **Relevant** stage, the first custom stage every pipeline is seeded with), **Reject** the ones that aren't a fit (they move to Rejected, recoverable anytime, nothing is deleted).
She approves Copper Kettle Foods and four others. She rejects a beverage *brand* that outsources all its production: technically food and beverage, but it doesn't run its own plants, so there's no boiler to replace.
Then she makes the board hers with custom stages between Relevant and Done, **"Reached out"** and **"Site visit scheduled"**, matching how Calyx actually sells. Pioneer doesn't impose a sales methodology; after leads land, the board is your working surface. (The Done column is always there as the finish line; rename it to "Pilot signed" if that's what done means to you.)
{/* SCREENSHOT: the board mid-triage: a lead card being dragged from Leads to Relevant, with custom stages "Reached out" and "Site visit scheduled" visible between Relevant and Done */}
Here's why triage matters beyond bookkeeping: **every move is teaching.** Approvals and rejections are ground truth about what a good lead looks like, stronger evidence than anything the algorithm believed. A lead you approve even though it wasn't relevant tells Pioneer your criteria are too strict; a rejected relevant lead says the opposite. Pioneer uses exactly this signal in the next step. And not only there: when Maya asks for more leads later, the discovery run reads her board directly (more like what she kept, none of what she rejected on sight).
## Steer the next batch in plain language
Maya's first batch had a pattern: too many beverage brands, not enough actual processors. She doesn't need to hand-edit criteria to fix that. In the Preferences column:
- **Recommended actions:** Pioneer analyzes the pipeline (your criteria, your properties, and how leads actually scored) and suggests up to three concrete improvements. Clicking one shows the exact change for review; nothing is ever applied silently.
- **Steering:** the text box at the bottom of the column takes plain-language instructions. Maya types: *"fewer beverage brands, more processors that run their own plants."* Pioneer turns that into a specific criteria change and shows it to her before anything is applied.
{/* SCREENSHOT: the Preferences column with three Recommended actions chips visible and a steering instruction typed into the input at the bottom */}
Review-before-apply is deliberate everywhere here: the criteria are your contract with Pioneer, and Pioneer never rewrites the contract behind your back. The full refinement loop (review, spot the pattern, refine, run again) is covered in [Refining Your Pipeline](/docs/guides/refining).
## Ask for more leads, or bring your own
With sharper criteria, Maya wants a bigger batch. The control lives where leads land: the **more leads** button in the Leads column header. It offers two paths:
- **We find them for you:** pick a count and click **Find leads**. Discovery runs again with everything the pipeline has learned.
- **Upload your own list:** paste anything, whether rows copied from a spreadsheet, company names, emails, or links. Maya pastes six processors from a conference attendee list. Each line becomes a lead that gets the exact same research and qualification as discovered ones; origin never changes rigor. See [Importing Your Own Leads](/docs/features/import).
{/* SCREENSHOT: the "more leads" popover open from the Leads column header, showing the "We find them for you" count picker, the Find leads button, and the "Upload your own list" option below */}
A pipeline runs one lead-adding job at a time, a search or an import, never both at once, so progress stays legible and nothing is double-spent. Repeat the loop (generate, triage, steer, generate) and fifty qualified leads is a matter of a few passes, not a few weeks.
## Find the person you'd actually email
A qualified company is half an answer. Maya's real question about Copper Kettle is operational: *who owns the boiler decision?*
[Properties](/docs/features/properties) are custom research questions Pioneer answers for every lead in the pipeline. From the Preferences column editor, Maya adds three: **"Primary process fuel"** (text), **"Number of facilities"** (number), and the important one, **"VP of Operations"** with the type set to **Person**. A Person property doesn't return a text snippet: Pioneer identifies the actual human in that role at each company and researches them.
On the Copper Kettle card, the property resolves to **Dan Whitfield**, who appears as a clickable chip. His contact card shows a short **About** (Maya's personalization material: he spoke on an industrial-electrification panel in March), his **email** with a verification badge showing it's deliverable, his **LinkedIn**, and his other channels.
{/* SCREENSHOT: a person contact card open from a lead: About section, email with a verified badge, LinkedIn and other channels listed, with source links visible */}
Every detail on that card was **found, never guessed**. Emails are never pattern-guessed from name@company conventions; each channel comes from a real page Pioneer actually read, and emails are verified for deliverability before you spend a send on them. If a channel couldn't be found, the card says so: an honest blank beats a confident mistake, because one wrong email costs more than a hundred empty fields. The full story of champions and contact cards is in [Finding the Right People](/docs/guides/people).
## Find a warm path to the person you want to reach
Maya has a name, a profile, and a verified email. But before she cold-emails, it's worth checking whether someone she knows can introduce her. On any person card, click **Find warm connection**: Pioneer searches your network for people who know this person, and suggests a short opening. A warm introduction converts far better than a cold one, and Pioneer does the matching work.
Read more about [My Network](/docs/features/my-network).
## Export your board and go get the meeting
Time to act on all of it. Maya clicks **Export** in the header of the Relevant stage. Pioneer downloads a single CSV: every analyzed lead with its name, website, its relevance tier, its one-line summary, a link back to its full research, and one column for every property. Dan Whitfield doesn't export as an ID or a blob: person properties are split into separate columns for name, LinkedIn, email, and other contact details, ready for a CRM or an outreach tool with zero cleanup.
{/* SCREENSHOT: the Export button in the Relevant stage header, with the downloaded CSV open showing property columns and the person split into name / LinkedIn / email columns */}
She also has the results email from each discovery run: summary on top, two CSVs attached, her relevant leads, and the leads that weren't relevant. The second file is worth a skim: seeing what got filtered out is the fastest way to check your criteria are drawing the line where you meant to. Details in [Exporting Your Leads](/docs/features/export).
Her co-founder wants the board itself rather than the spreadsheet, and he has no Pioneer account, so Maya clicks **Share** in the pipeline header and emails him his own read-only link: [Sharing a Pipeline](/docs/features/sharing).
Maya's first week with Pioneer ends with a board of qualified processors, a named decision-maker with a verified email on each approved lead, and a spreadsheet her outreach runs on. That's the whole journey, and every pass through the loop makes the next one better.
## Where to go deeper
Each step of this walkthrough has a page that goes further:
- [Creating Your First Pipeline](/docs/first-pipeline): the creation flow, step by step
- [Criteria](/docs/concepts/criteria): writing MUST and SHOULD criteria that actually work
- [How Discovery Works](/docs/concepts/discovery): what Pioneer does differently from a database
- [Refining Your Pipeline](/docs/guides/refining): the review, steer, regenerate loop
- [Finding the Right People](/docs/guides/people): champions, contact cards, and verified channels
- [Importing Your Own Leads](/docs/features/import) and [Exporting Your Leads](/docs/features/export): getting leads in and out
- [Sharing a Pipeline](/docs/features/sharing): a read-only view of the board for people outside Pioneer
- [My Network](/docs/features/my-network): warm paths and asks from the people you already know
- [Getting High-Quality Leads](/docs/guides/quality): habits of teams whose boards stay good
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Create Your First Pipeline
URL: https://usepioneer.ai/docs/first-pipeline
By the end of this page you'll have a running pipeline: Pioneer searching the web for leads that match your description, qualifying each one against your rules, and landing them on your board ready for review.
Want the extended version, one real pipeline followed all the way to an exported list, step by step? Read [From signup to your first 50 qualified leads](/docs/first-50-leads). This page is the fast path.
{/* Diagram source: /public/images/docs/pipeline-lifecycle.svg (edit the SVG, re-export the PNG at 2x).
Contents: left-to-right flow: "Describe (what you are looking for)" → "Set criteria (MUST and
SHOULD)" → "Discovery (Pioneer searches the web)" → "Qualification (each lead scored)" →
"Your board (leads ready to review)" (highlighted in Pioneer blue), with a dashed feedback
arrow from the board back to Set criteria labelled "Refine criteria and run again". */}
## Let your agent do the setup with you
Pioneer is built to work with the AI agent you already use (Claude, ChatGPT, Codex, or any other). During signup you'll get a short setup message you can paste straight into your agent, and your agent will guide itself through connecting to Pioneer; it can even create this first pipeline for you. The same message is one click away later, via the **ask your agent to do it** prompt on the `/pipelines` page.
The message points at [Use Pioneer With Your Agent](/docs/agents), the full agent setup guide. Credentials are minted only when you ask, and shown exactly once.
Prefer to set everything up yourself? Everything on this page works by hand too; the agent path is a shortcut, not a requirement.
## Your first pipeline might already exist
Some teams sign up and find a pipeline already sitting in their account, built by the Pioneer team, with real leads researched and qualified for their business. If that's you, here's what to know:
**What it is.** We sometimes build a pipeline for a company we think Pioneer can help, before anyone there has an account. When someone signs up with a work email from that company, the pipeline is automatically handed to their workspace.
**It's yours now.** Everything in it (the description, criteria, properties, and every researched lead) is fully editable, exactly as if you'd built it yourself. Nothing in it is demo data: the leads are real, researched against criteria we guessed for your business.
**Our guess, your call.** We wrote the description and criteria from public information about your company. Treat them as a first draft: skim the leads, then adjust the criteria in the **Preferences** column so they match how *you* actually qualify. Refining is the whole point. See [Refine Your Pipeline](/docs/guides/refining).
**Start by reviewing, not creating.** The fastest way to get value is to open the pipeline, approve a few leads that look right, reject a few that don't, and steer from there. You can always create more pipelines alongside it. The rest of this page walks through building one from scratch.
## Start from a recipe or from scratch
From the `/pipelines` page, you have two options:
**From a recipe:** Click **Try this** on any suggested recipe. Recipes are pipeline ideas Pioneer generates from your stated purpose, deliberately specific and narrow, because "Series A battery-recycling startups in the EU" makes a far better pipeline than "companies in energy". A recipe pre-fills everything; you can still customize before creating.
**From scratch:** Expand the "Create a custom pipeline" section and describe what you're looking for.
Either way, the two decisions that matter are the next two steps: the description and the criteria. Everything Pioneer finds flows from them.
The two paths to create a pipeline: recipe or from scratch
## Describe what you're looking for
Write a natural-language description of the leads you want to find:
**Examples:**
- "Early-stage fintech startups building payment infrastructure"
- "VP-level marketing executives at Series B+ B2B SaaS companies"
- "Climate tech investors who've made investments in the last 12 months"
- "Design agencies that specialize in enterprise software products"
Be specific. Pioneer follows your words, not the intent behind them. "Fintech startups" casts a wide net; "B2B fintech startups building payment infrastructure for marketplaces" aims the search. Each level of detail narrows where [discovery](/docs/concepts/discovery) spends its effort.
## Split deal-breakers from preferences
Criteria are the rules Pioneer uses twice: to guide what it searches for, and to judge every lead it finds. They come in two tiers, and the split matters more than anything else on this page:
**MUST criteria** are deal-breakers. A lead that fails any MUST is not relevant, mechanically, no exceptions.
- "Must be a B2B company (not consumer)"
- "Must have raised funding"
**SHOULD criteria** are preferences. They improve a lead's ranking but never disqualify it.
- "Should have at least 50 employees"
- "Should have a US presence"
Why two tiers: if everything were a MUST, every preference would become a veto and almost nothing would qualify; if everything were a SHOULD, your actual deal-breakers would be negotiable. Put things you'd walk away over in MUST, and everything else in SHOULD.
Start with 3–5 criteria and expect to adjust after the first batch. Refining against real results is faster than trying to write perfect rules upfront. The full guide: [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria).
## Let Pioneer work
Once you create the pipeline, discovery begins:
1. **Pioneer searches the web.** Not one query, but iterative exploration: multiple strategies, promising results followed deeper, the approach adjusted by what it finds.
2. **Each lead is qualified.** Every discovered lead is evaluated against your criteria, with evidence and reasoning recorded per criterion.
3. **Leads land on your board.** Qualified leads appear in the **Leads** column, best matches first, while in-flight research shows live in the **Incoming** box above it.
Discovery happens in the background, and you don't need to babysit it: when the run finishes, Pioneer emails you a summary with your leads attached as CSV files. Close the tab; the results will find you. See [Export Your Leads](/docs/features/export).
## Review your first batch
Click any lead to open its research:
- **Summary:** a concise overview of who or what this lead is. Read this first.
- **Criteria results:** how the lead scored against each of your criteria, with the evidence Pioneer found. How to read them: [Read a Lead's Research](/docs/concepts/leads).
Then make the call:
- **Approve** leads worth pursuing. They move to the **Relevant** stage, the first custom stage every pipeline is seeded with.
- **Reject** leads that aren't a fit. Rejected leads are recoverable, never deleted.
- **Drag** approved leads through your custom stages as you work them.
Don't agonize over borderline calls. Your approvals and rejections are feedback, and the next step turns that feedback into better results.
## Refine and run again
Your first batch is a starting point, not a verdict. React to it:
**Too few leads?**
- Broaden your description
- Convert some MUST criteria to SHOULD
- Make criteria less restrictive
**Too much noise?**
- Make your description more specific
- Add MUST criteria for real deal-breakers
- Tighten existing criteria
The **Preferences** column on your board is where refinement lives. Pioneer suggests concrete improvements after each batch, and you can steer in plain language ("exclude agencies", "earlier stage only"). Two refinement passes usually close the gap between what you asked for and what you meant. The full playbook: [Refine Your Pipeline](/docs/guides/refining).
## Next steps
- [From signup to your first 50 qualified leads](/docs/first-50-leads): the same journey, end to end in full detail
- [Your Pipeline & Board](/docs/pipelines): what every column does and why
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): writing criteria that work
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Your Pipeline & Board
URL: https://usepioneer.ai/docs/pipelines
This page is the map of the surface you'll use most. After it, you'll know what a pipeline actually is, what every column of the board does and why it's there, and why each move you make on the board makes Pioneer better.
## A pipeline is a question you ask once
A **pipeline** is a standing research project, a question you ask once and Pioneer keeps answering. "Find climate tech startups for partnership" is one pipeline. "Discover angels investing in AI" is another.
Each pipeline has three teachable parts:
- **A description:** what you're looking for, in your own words
- **[Criteria](/docs/concepts/criteria):** what makes a lead a good fit, with MUST rules for deal-breakers and SHOULD rules for preferences
- **[Properties](/docs/features/properties):** the data you want researched on every lead, from "headquarters city" to "VP of Operations"
Keep one pipeline per goal. Criteria that try to describe two different targets at once qualify neither well; two focused pipelines beat one blurry one.
## Start on the /pipelines page
When you navigate to `/pipelines`, you'll see:
### Suggested recipes
Based on your purpose (set during onboarding), Pioneer generates personalized pipeline recipes: specific, narrow starting points tailored to your goals.
- Click **Try this** to pre-fill a pipeline with that recipe
- Click **Not for me** to dismiss it. Pioneer learns from the dismissal and suggests differently next time.
- Edit your purpose to change the direction of all suggestions
Your purpose is worth a sentence of care, because it powers every recipe. "Sales stuff" gives Pioneer nothing to work with; "finding enterprise customers in financial services for our compliance automation platform" gives it everything.
**Example purposes:**
- "Lead generation for enterprise SaaS deals"
- "Finding seed investors for my climate tech startup"
- "Building partnerships in the fintech ecosystem"
- "Sourcing API vendors for our data pipeline"
### Create a custom pipeline
If none of the recipes fit, create one from scratch: describe what you're looking for, define your criteria, and Pioneer starts discovering. Step-by-step: [Create Your First Pipeline](/docs/first-pipeline).
Prefer to work through your agent? Use the **ask your agent to do it** prompt on this page: it shows the one-line setup message your agent needs, and your agent can create this pipeline for you end to end. See [Use Pioneer With Your Agent](/docs/agents).
## The board, column by column
Each pipeline is a board, with leads flowing left to right. Every column exists for a reason:
- **Preferences:** the leftmost column, and not a lead column at all. It's your pipeline's control center. It shows what you're looking for (description, criteria, properties) at a glance, surfaces Pioneer's suggested refinements, and holds the steering box where you type corrections in plain language. It sits beside your leads on purpose: what the pipeline looks for, how to correct it, and what it produced belong side by side. Click the pencil to edit, or collapse the column for more room. Full guide: [Refine Your Pipeline](/docs/guides/refining).
- **Incoming:** a box directly above the Leads column showing leads Pioneer is researching *right now*, each with live progress. It's visible because watching leads materialize is how you learn what Pioneer is doing for you, and it's where stuck or failed leads show a warning and a **Retry** button instead of silently vanishing.
- **Leads:** where researched leads land, best matches first. Leads that are **relevant** (every MUST criterion met) sort highest, followed by **mostly relevant** and **partially relevant**. This column is the handoff point: Pioneer's work ends here and yours begins. The **more leads** button in the column header is where you ask Pioneer for another batch or [upload your own list](/docs/features/import).
- **Relevant:** leads you've approved. This is the first custom stage, seeded for every pipeline because approving a lead needs to land somewhere. Rename it to match your process like any other stage.
- **Custom stages:** your own columns between Relevant and Done ("Contacted", "Meeting Scheduled", "Proposal Sent"). Pioneer deliberately doesn't impose a sales methodology. After approval, the workflow is yours, so the stages are yours too. Deleting a stage never deletes its leads.
- **Done:** the finish line. Rename it to whatever fits your workflow ("Won", "Closed").
- **Rejected:** leads you passed on. Nothing in Pioneer is ever deleted by a board move, so you can bring any rejected lead back whenever you want.
The board is live: new leads and column changes appear in real time, no refresh needed.
When someone outside Pioneer needs to see the board rather than a spreadsheet (an investor, an advisor, a partner), **Share** in the pipeline header emails them a personal read-only link, or creates one you can copy and send yourself, no account required: [Sharing a Pipeline](/docs/features/sharing).
Leads flow left to right through board columns
## Every move teaches Pioneer
Approving and rejecting isn't just bookkeeping. Every move is ground truth about what a good lead looks like, and your judgment outranks anything the algorithm believed. A lead you approve despite a middling score tells Pioneer your criteria are stricter than your actual taste; a rejected lead that was **relevant** says the opposite.
Pioneer turns that feedback into concrete suggestions: after each discovery run, the **Preferences** column offers up to three **Recommended actions**, specific criteria or property changes, each shown for your review before anything is applied. And the steering box takes plain-language directions ("more hardware companies, fewer resellers") and converts them into a criteria change you approve or discard.
This loop (review, notice the pattern, refine, run again) is where Pioneer pipelines go from decent to excellent. It gets its own guide: [Refine Your Pipeline](/docs/guides/refining).
## Next steps
- [Create Your First Pipeline](/docs/first-pipeline): the step-by-step walkthrough
- [Read a Lead's Research](/docs/concepts/leads): how to review what lands on the board
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): the rules behind everything above
- [Sharing a Pipeline](/docs/features/sharing): a read-only view for people outside Pioneer
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Teach Pioneer What a Great Lead Looks Like
URL: https://usepioneer.ai/docs/concepts/criteria
A criterion is a plain-language description of something you're looking for, like "must handle consumer financial data" or "should have open compliance roles". It is not a database filter. Nothing is being matched against a column somewhere; Pioneer searches by your descriptions and then researches every lead it finds to judge how well that lead actually fits each one.
Criteria are therefore how you teach Pioneer your taste. By the end of this page you'll know how to write descriptions Pioneer can act on, how it judges each one against each individual lead, how the relevance verdict is decided, and how to sharpen your criteria as real results come in.
## Start from an example
Say you sell compliance software to fintech companies. A working set of criteria looks like this:
```
MUST:
- Must be a B2B fintech company selling lending, banking, or payments software
- Must handle consumer financial data
- Must have a live product with real customers
SHOULD:
- Should have raised Series A or later funding
- Should have open compliance or risk roles
- Should be based in the US
```
Read that list top to bottom and you know exactly what this team wants, and so does Pioneer. The MUSTs are non-negotiable; the SHOULDs describe the *best* version of a relevant lead. Every rule is something the public web can answer: product pages, funding announcements, job postings. That's the standard the rest of this page teaches.
## Criteria work twice: finding and judging
Every criterion does double duty, and this is why they're worth more care than anything else you write:
1. **Guiding discovery.** Criteria shape which corners of the internet Pioneer explores. "Must have raised Series A funding" sends Pioneer to funding announcements; "should have open compliance roles" sends it to career pages.
2. **Qualifying leads.** Every lead is researched against every criterion, with evidence gathered and reasoning recorded for each judgment.
One definition of "a good lead," used in both places, so when you improve a criterion, the finding *and* the judging improve together. Better criteria mean better leads. It's that direct.
## Pioneer judges every criterion against every lead
This is the mechanism underneath everything else on this page, and it's the opposite of box-ticking.
For each lead, Pioneer takes your criteria one at a time, reads what its research turned up, and makes a graded judgment: **how strongly does this lead match what this criterion is asking for?** Direct, unambiguous evidence on the lead's own pages is a strong match. Clearing the bar on one indirect signal is a moderate one. A tangential connection is weak. Alongside that judgment it records a verdict (met, not met, or inconclusive) and the reasoning and evidence behind both, which is what you read on the card.
The strength of match is judged separately from the verdict, and that's what makes it useful: a criterion can pass on thin evidence and still register as a weak match, and a criterion can fail while registering real partial alignment. Nothing here is precomputed. The same criterion produces a different judgment on every lead, because it's judged against that lead's actual evidence.
One consequence worth internalizing: **a lead that only weakly matches your criteria loses ground even when it technically passes them.** It's also why a vague description is expensive: "should be innovative" gives Pioneer nothing concrete to judge a lead against, so it contributes noise to every lead's position.
## MUST and SHOULD are how you say what matters
The two tiers are how you *tell* Pioneer what's non-negotiable and what's merely preferred. The graded judgment above is how Pioneer *applies* that to each lead.
### MUST criteria
Your deal-breakers, and the relevance gate. A lead needs to meet **all** of them to be relevant.
**Examples:**
- "Must sell to businesses, as evidenced by enterprise pricing, case studies, or a sales-contact page"
- "Must have raised venture funding"
- "Must have a presence in North America"
Use MUST only for things that, if missing, mean the lead isn't worth your time at all.
### SHOULD criteria
What you value without requiring it. Each SHOULD feeds the ranking through how strongly a lead matches it, but none of them can disqualify a lead.
**Examples:**
- "Should have a team of at least 10 people"
- "Should have published content about sustainability"
- "Should be using modern cloud infrastructure"
Why the two tiers exist: collapse them and either every preference becomes a veto (you starve the pipeline) or every requirement becomes negotiable (you drown in noise). Keeping the contract and the taste separate is what makes both useful.
MUST criteria are deal-breakers; SHOULD criteria are preferences
## Relevance is a rule, not a vibe
Relevance is mechanical: **a lead is relevant if every MUST criterion is met, mostly relevant if it meets most of what matters, and partially relevant otherwise.** The tier is calculated from the criteria results alone: no AI override, no fuzzy weighting of your deal-breakers. You wrote the standard; the standard decides. A system that quietly overrode your stated deal-breakers would teach you that the controls are decorative, so it never does.
Each criterion gets a verdict, with the reasoning and evidence behind it:
| Result | Meaning |
|--------|---------|
| **Met** | Evidence found that this criterion is satisfied |
| **Not Met** | Evidence suggests this criterion isn't satisfied |
| **Inconclusive** | Nothing public establishes it either way |
The third row is the one to internalize, because the two strengths treat it differently. On a **SHOULD**, inconclusive is an honest "don't know" and simply doesn't move the ranking. On a **MUST**, it counts as **not met** and disqualifies the lead: a MUST passes only on affirmative evidence that the lead satisfies it. That asymmetry is deliberate, since a gate that swings open whenever Pioneer found nothing isn't a gate. The consequence for you: a MUST that nothing findable can confirm fails across your entire pipeline. See [Write rules that can be confirmed, not just contradicted](#write-rules-that-can-be-confirmed-not-just-contradicted).
SHOULD criteria never make or break relevance. They act on the ranking instead. A lead's position in the Leads column comes from adding up how strongly it matched each of your criteria, with a met MUST weighing substantially more than a SHOULD, enough that relevant leads always sit above leads that failed a deal-breaker, while within each group the strongest evidence rises first. Because every strength is judged per lead, the ordering adapts to what Pioneer actually found rather than to a formula you have to learn.
So when a lead you like isn't relevant, there's exactly one place to look: which MUST failed, and whether you actually believe that rule. And when a relevant lead sits lower than you expected, the answer is in the strengths, not the verdicts: it passed everything, but weakly. How to read both on a real lead: [Read a Lead's Research](/docs/concepts/leads).
## Write rules the web can answer
Pioneer evaluates criteria through web research, so a good criterion is one the public web can verify.
### Be specific, not vague
- "Should be a good company" → "Should have been in operation for at least 2 years"
- "Must be in tech" → "Must sell a software product, as evidenced by product or pricing pages"
Vague criteria fail twice: they can't guide the search, and they can't be evaluated with evidence.
### Base criteria on discoverable information
**Usually discoverable:**
- Company size (LinkedIn, Crunchbase)
- Industry/vertical (website, press coverage)
- Funding status (Crunchbase, press releases)
- Geographic presence (website, job postings)
- Technology stack (job postings, case studies)
**Often not public:**
- Exact revenue numbers (unless disclosed)
- Internal processes
- Specific budget allocations
A criterion the web can't answer comes back inconclusive on every lead, which tells you nothing, and fails every lead if you made it a MUST. Rewrite it around a public signal: instead of "must have budget for tooling," try "should be actively hiring engineers" (a company that's hiring is spending).
### Write rules that can be confirmed, not just contradicted
Research can establish that something is true. It can never establish that something is universally false, since "we found nothing" is not proof of absence. So a criterion phrased as an exclusion has no positive test to pass, and every lead fails it, including the leads that genuinely satisfy it.
A real example. A pipeline for companies that *buy* carbon credits carried this MUST:
- "Must not be a carbon credit provider, registry, or certification body"
There is no web page that confirms a company isn't one of those things, so the criterion could only fail, and it disqualified exactly the buyers the pipeline existed to find. Two ways to fix it:
- **Say the positive fact you actually want.** "Must purchase carbon credits to offset its own emissions, as evidenced by a sustainability page, ESG report, or named offset partner." Now there's something to find, and providers don't have it.
- **Put the exclusion in the pipeline description instead of a criterion.** Your description guides discovery, so "we're looking for buyers, not credit providers or registries" steers the search without becoming a gate no lead can clear.
The same trap catches "must have no outsourced support," "must not be an agency," and "must be free of legacy infrastructure." If you can't name the page that would prove a criterion true, rewrite it.
### Test one thing per criterion
Instead of "Must be a Series A+ company in fintech with at least 50 employees", write three rules:
- "Must have raised Series A or later funding"
- "Must be in the fintech industry"
- "Should have at least 50 employees"
Separate rules get separate verdicts, so when a lead falls short, you can see exactly where, and fix exactly that.
### Start with 3–5
Too few criteria and results run broad, leaving you to filter by hand. Too many and results narrow toward zero, missing strong matches. Start with 3–5 and let real results tell you which way to adjust.
## Sharpen criteria as results arrive
Your first criteria won't be perfect, and they don't need to be. Pioneer helps you refine them right on the board, in the **Preferences** column:
- **Recommended actions:** Pioneer analyzes your pipeline and suggests up to three concrete improvements to your criteria or properties. Click one to review the exact change before it's applied, or hit the refresh icon for a new set.
- **Steering:** type what you want in plain language ("more hardware companies", "exclude agencies") into the box at the bottom of the Preferences column. Pioneer turns it into a criteria change for you to review.
- **Direct editing:** click the pencil at the top of the Preferences column and edit the rules yourself.
When your criteria change, Pioneer re-checks your existing leads against the updated rules and uses them for everything it discovers next. Refinement applies to the whole pipeline, not just future leads. The full playbook, with a worked example: [Refine Your Pipeline](/docs/guides/refining).
## Two worked setups
### Finding enterprise customers
```
MUST:
- Must sell to enterprises, as evidenced by named enterprise customers or case studies
- Must have raised at least Series A funding
- Must have a presence in the United States
SHOULD:
- Should have 100+ employees
- Should have published case studies on their website
- Should have a dedicated sales team
```
### Finding investors
```
MUST:
- Must be an active investor (made investments in the last 2 years)
- Must invest in seed or Series A stage
- Must invest in B2B software
SHOULD:
- Should have invested in companies similar to ours
- Should be based in the Bay Area or NYC
- Should have a clear focus area that includes our space
```
More setups across six use cases: [Example Pipelines](/docs/guides/use-cases).
## Next steps
- [How Pioneer Finds Leads](/docs/concepts/discovery): what your criteria actually steer
- [Refine Your Pipeline](/docs/guides/refining): the loop that makes criteria great
- [Create Your First Pipeline](/docs/first-pipeline): put criteria into practice
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# How Pioneer Finds Leads
URL: https://usepioneer.ai/docs/concepts/discovery
You don't need this page to use Pioneer. But once you know how discovery actually works, you'll write sharper descriptions and criteria, you'll understand why leads keep arriving hours after you start a search, and you'll know exactly what kind of lead Pioneer can find that no database can.
## Pioneer searches the web, not a database
Most lead-generation tools are databases: a fixed set of records you filter. If your ideal lead isn't in the database, or the signal you care about isn't a column, you're out of luck.
Pioneer searches the **open web**. There's no pre-existing dataset limiting what you can discover: if the information exists publicly (a press release, a job posting, a case study, a conference agenda), Pioneer can find it and use it. That's why criteria like "should have open compliance roles" or "must have published technical papers" work in Pioneer and don't work anywhere else: no database has that column, but the web has the answer.
Pioneer's discovery process, from understanding your goal to handing off qualified leads
## One instruction becomes many searches
Take a single criterion: *"Must have raised Series A funding."* Pioneer doesn't just append "Series A" to a query. It looks for funding announcements, checks press coverage, cross-references what it finds, and lets each result suggest where to look next.
That's the pattern for the whole search. Pioneer:
- Runs multiple search strategies, not one query
- Explores promising results deeper
- Follows related links and references
- Adjusts its approach based on what it finds
- Continues until it's confident it has covered the space
This is why discovery takes time, and why that's a feature: initial leads usually arrive quickly, but thorough coverage of a space takes hours, not seconds. A tool that answers instantly is querying a database; a tool that keeps delivering all afternoon is doing research.
## Every candidate has to prove its identity
Before anything becomes a lead on your board, it passes three checks, each one there because its absence would fill your board with junk:
1. **It must be the right kind of thing.** If your pipeline looks for companies, a *listicle about* companies doesn't qualify, and neither does a person. Pioneer checks that each candidate is actually the kind of entity you're looking for.
2. **It must resolve to its own web address.** Search results usually point at pages *about* a company: a LinkedIn page, a directory entry, an aggregator. Pioneer resolves each candidate to its own primary website, because all further research starts from that address, and research aimed at a directory page would research the directory.
3. **It must be new.** Candidates are deduplicated against leads already in your pipeline, so the same company doesn't land twice. Dedup checks more than the URL: a company that enters through its own website and through a directory profile (like a Crunchbase or an accelerator listing) resolves to two different URLs, but Pioneer recognizes them as the same entity and keeps only one. The fingerprint is multi-faceted (normalized name, domain, URL) and includes fuzzy matching, so similar names that refer to the same company are caught.
## Leads arrive qualified, not raw
Discovery and qualification aren't separate steps you manage. Every candidate that passes the identity checks is researched against your [criteria](/docs/concepts/criteria) before it reaches you: evidence gathered per criterion, a summary written, a verdict recorded with its reasoning. What lands in your Leads column is a researched answer, ready to judge. How to read one: [Read a Lead's Research](/docs/concepts/leads).
## What Pioneer can find, and what it can't
**If it's public on the internet, Pioneer can find it:**
- **Companies and startups:** websites, Crunchbase profiles, press coverage
- **People:** LinkedIn profiles, personal websites, speaker bios
- **Organizations:** nonprofits, agencies, institutions
- **Investors:** fund websites, portfolio pages, news coverage
- **Anything else:** if it has a web presence and matches your criteria
**What it can't:**
- **Private information:** data that isn't publicly available online
- **Paywalled content:** information behind subscriptions or logins
- **Very recent information:** there's a lag between publication and searchability
This boundary is worth internalizing when you write criteria: a rule about private information comes back Inconclusive everywhere. See [Write rules the web can answer](/docs/concepts/criteria#write-rules-the-web-can-answer).
## Discovery and import get the same treatment
Pioneer offers two ways to add leads, and they converge:
**Discovery (automatic):** describe what you're looking for; Pioneer finds candidates you don't know about yet.
**Import (manual):** paste a list of names, links, or emails; Pioneer researches and qualifies each one exactly as if it had discovered them, with the same enrichment, the same criteria verdicts, and the same board.
Use both in the same pipeline: discovery to explore the space, [import](/docs/features/import) to add referrals, conference contacts, or an existing list. A lead's origin never changes its quality.
## Help the search help you
**Be specific in your description.** "Fintech startups" is okay. "B2B fintech startups building payment infrastructure for marketplaces" is better; every extra qualifier redirects real search effort.
**Write criteria as search hints.** Criteria don't just filter. They aim the exploration. "Must have raised Series A" tells Pioneer where to look, not just what to accept.
**Give it time.** Check back after a few hours for the full picture. And you don't have to wait around: when a run finishes, Pioneer emails you the results. See [Export Your Leads](/docs/features/export).
## Next steps
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): write the rules that steer all of this
- [Import Your Own Leads](/docs/features/import): when you already have the list
- [Refine Your Pipeline](/docs/guides/refining): make each search better than the last
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Read a Lead's Research
URL: https://usepioneer.ai/docs/concepts/leads
A **lead** is one candidate answer to your pipeline's question: one company, one person, one organization. Every lead on your board arrives already researched: summarized, evaluated against each of your criteria, with evidence attached. This page shows you how to read that research fast and act on it well.
(For the board itself, and what each column does, see [Your Pipeline & Board](/docs/pipelines). This page is about the lead in front of you.)
## A lead is a researched answer, not a database row
Leads are born two ways, [discovered](/docs/concepts/discovery) by Pioneer or [imported](/docs/features/import) by you, and both get identical treatment: Pioneer reads the lead's web presence, researches evidence for every criterion, writes a summary, and fills in your [properties](/docs/features/properties). What lands on your board is the finished dossier, not a name to go research yourself.
## Watch it arrive in Incoming
While Pioneer works, the lead sits in the **Incoming** box directly above the Leads column, with a live progress indicator. When research finishes, it lands in the **Leads** column, sorted by how well it matches, with leads that are **relevant** (all MUST criteria met) highest, strongest matches first.
If research on a lead stalls or fails, Pioneer tells you instead of hiding it: a warning icon appears next to the lead. Hover to see what went wrong, and click **Retry** to run it again. Retrying is safe; it re-runs the research without creating a duplicate. Failures stay visible because a lead that silently vanished would make you doubt every lead that remained.
## Open the card: read the summary first
Click any lead to see its detail view. Start with the **Summary**, a concise overview of who or what this lead is. It's the TL;DR that answers "is this worth another 60 seconds?" before you dig into the verdicts.
The summary's first words tell you where the lead stands. **"Relevant because…"** means it met every one of your MUST criteria: the same rule as the recommendation. **"Mostly relevant because…"** and **"Partially relevant because…"** mean at least one deal-breaker failed; the difference between them is how much of your criteria the lead did match. The opener is computed from the criteria results, not written freehand, so it always agrees with the verdicts below it.
## Check the verdicts, not just the badge
Below the summary sit the **criteria results**, one verdict per criterion, each with Pioneer's reasoning and the evidence it found:
- **Met:** evidence found that this criterion is satisfied
- **Not Met:** evidence suggests this criterion isn't satisfied
- **Inconclusive:** not enough public information to determine
The verdicts are where the actual intelligence lives. A lead's badge tells you *what* Pioneer concluded; the verdicts tell you *why*, and reading the why is what lets you catch a mis-written criterion, spot the evidence worth citing in your outreach, and trust the leads you didn't have time to double-check.
**Inconclusive deserves special attention, especially on a MUST.** A MUST passes only on affirmative evidence, so an inconclusive MUST counts as not met and disqualifies the lead; on a SHOULD it just doesn't move the ranking. One inconclusive verdict on one lead is noise. The same criterion inconclusive across many leads means the rule isn't answerable from public information, or is phrased so that no evidence could confirm it; rewrite it around a signal the web can verify. See [Write rules that can be confirmed, not just contradicted](/docs/concepts/criteria#write-rules-that-can-be-confirmed-not-just-contradicted).
## Relevant, mostly relevant, or partially relevant: mechanical, from the criteria
A lead is **relevant** if every MUST criterion is met, **mostly relevant** if it meets most of what matters, and **partially relevant** otherwise. The tier is mechanical: every MUST passed = relevant; below that, the share of criteria the lead satisfies decides mostly vs. partially. The opener you see on the card ("Relevant because…", "Mostly relevant because…", "Partially relevant because…") follows from the tier, and the rule never changes it: no AI override, no fuzzy weighting of your deal-breakers. You wrote the standard; the standard decides.
The mechanical rule makes disagreements easy to diagnose: open the lead, find the MUST that failed, read the evidence. Two different conclusions follow:
- **Pioneer was right:** the lead genuinely fails your rule. Your criteria are working; trust the badge a little more.
- **Your criterion is wrong:** the rule is stricter than what you actually believe. Fix the criterion, not the lead: [Refine Your Pipeline](/docs/guides/refining).
## Make the call: nothing is ever deleted
From the board or the detail view:
- **Approve** leads worth pursuing. They move to the **Relevant** stage, the first custom stage every pipeline is seeded with.
- **Reject** leads that don't fit. They move to **Rejected**, fully recoverable, and the card remembers which stage it was rejected from.
- **Drag** approved leads through your custom stages as you work them.
Reject freely: no board move deletes anything, and clearing the barely relevant leads keeps your Leads column focused on decisions you haven't made yet. Every one of these calls is also feedback: your approvals and rejections shape Pioneer's refinement suggestions *and* directly steer what the next discovery run searches for. See [how the board teaches](/docs/guides/refining#your-board-moves-teach-on-their-own). Your judgment outranks the algorithm's score.
A lead's journey through the pipeline, from incoming to done
## Track outreach state with notes
The right-hand pane of any open lead shows the **Notes Bar**: a place to write outreach drafts, track activity, and record anything that keeps a deal moving. Notes are instant: write one, save, and it's on the lead, with no workflow run, no loading state, and no credit cost.
Notes are grouped by **name**, your choice: a draft email lives under "Draft email", a to-do under "Next call", and anything you leave unnamed goes to the lead's running **updates**. The name decides how a second note behaves:
- **Named notes are versioned.** A new note under the same name replaces the previous one. Your working email draft stays current; older drafts are hidden but kept.
- **Unnamed updates are a log.** Every note appends to a running record: "Sent intro email. Scheduled a meeting for Tuesday."
Notes are also in the **API and MCP**, so agents working on your behalf can read and write them through the same endpoints ([API reference](/docs/api)). A draft started in the app and a draft started by your agent converge on the same lead.
**Check notes before acting.** Whether you or an agent is working the lead, reading the notes first prevents contradicting or repeating what already happened.
## The lead vs. its data
**Leads** are the items themselves: companies, people, organizations. **Properties** are the data fields researched about each one: LinkedIn URL, headquarters, employee count, the person in the role you care about. When a lead is right but you need more from it, that's a properties job: [Enrich Leads with Properties](/docs/features/properties). And when a researched value is wrong or missing, you can fix it in place: [Correct Pioneer's Research](/docs/guides/accuracy).
## Next steps
- [Your Pipeline & Board](/docs/pipelines): the columns these leads flow through
- [Refine Your Pipeline](/docs/guides/refining): turn your approve/reject calls into better batches
- [Find the Right People](/docs/guides/people): from a good company to the human you'll talk to
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Import Your Own Leads
URL: https://usepioneer.ai/docs/features/import
You have a list (referrals, conference contacts, a CRM export) and you want Pioneer's research and qualification on it. This page shows you how to paste it in, what happens next, and how to get the cleanest results.
## Import when you have the list; discover when you don't
**Use [discovery](/docs/concepts/discovery) when:**
- You need to find new leads you don't already know about
- You want Pioneer to explore the web for you
- You're entering a new market or space
**Use import when:**
- You have an existing list of companies or people
- Someone referred prospects to you
- You want Pioneer's qualification on known targets
- You're migrating from another tool
Use both in the same pipeline: discover new leads while importing specific ones. Imported leads go through the exact same enrichment and qualification as discovered ones; the only difference is how they entered.
## Paste your list
1. Open your pipeline
2. In the **Leads** column header, click **more leads**
3. Choose **Upload your own list**
4. Paste your leads, one per line, and start the import
Pioneer creates a lead for each line and starts processing them right away.
The import flow, from pasting your list to qualified leads on the board
### What you can paste
You don't need a perfectly formatted file. The importer understands:
- **Links:** company homepages, LinkedIn company pages or profiles, personal websites
- **Names:** company or person names ("Acme Robotics", "Jane Rivera")
- **Emails:** work email addresses
- **Pasted tables:** copy rows straight from a spreadsheet or CRM export
Mix and match freely. Pioneer reads each line and figures out who the lead is. One lead per line works best.
### Importing a single lead
Same flow: open **more leads → Upload your own list** and paste just one line.
## Watch your import land
Imported leads arrive through the **Incoming** box directly above the Leads column, the same place discovered leads appear, so everything new lands in one spot.
Here's what you'll see, in order:
1. **"Reading your list…"** Pioneer parses what you pasted and works out who each line refers to. This usually takes a few seconds, even for long lists.
2. **Queued rows.** Each lead from your list appears immediately as a muted row marked *queued*, so you can confirm Pioneer read your list correctly before research even starts.
3. **Live progress.** Each queued row turns into a live one with a progress indicator as Pioneer researches it. If something goes wrong on a lead, a warning icon appears; hover for details and click **Retry**.
4. **Ready.** Finished leads move onto your board, qualified against your [criteria](/docs/concepts/criteria) and sorted like any other lead.
## One job at a time
A pipeline runs **one lead-adding job at a time**, either a search or an import, never both at once. If you try to start a second one, Pioneer tells you:
> "A lead import is already running for this pipeline. Wait for it to finish before adding more leads."
This keeps results clean: each batch finishes, lands on your board, and you can react to it before the next one starts. Once the running job finishes, start the next one from the same **more leads** control. If a job ever stalls, the block clears itself after a short while, so you won't be locked out.
Different pipelines are independent: a running import in one pipeline never blocks work in another.
## Get clean results
**Match your pipeline's focus.** If your pipeline is looking for B2B startups, import B2B startup URLs. Mismatched leads produce poor qualification results, because the criteria were written for something else.
**Links beat names.** Names and emails work, but a direct link (the lead's website or LinkedIn page) removes ambiguity: there's only one company at that URL.
**Check for duplicates.** Pioneer deduplicates by resolved URL. If you import the same lead twice via different URLs, they may appear as separate leads.
**Big lists are fine; react between batches.** There's no need to trickle leads in. Paste the whole list, let the import finish, review the results, then [refine your criteria](/docs/guides/refining) before importing or searching for more. One reviewed batch teaches Pioneer more than three unreviewed ones.
## Using import for qualification only
If you don't need discovery and just want Pioneer to qualify leads you already have:
1. Create a pipeline with criteria (no need for a discovery description)
2. Paste your lead list via **more leads → Upload your own list**
3. Let Pioneer qualify them
This gives you Pioneer's enrichment and qualification without the discovery step.
## Next steps
- [Enrich Leads with Properties](/docs/features/properties): extract the data you need from imported leads
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): the rules your imports are judged against
- [How Pioneer Finds Leads](/docs/concepts/discovery): complement your list with discovery
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Enrich Leads with Properties
URL: https://usepioneer.ai/docs/features/properties
A recommended company is half an answer. Properties get you the other half: the specific data you need on every lead (headquarters, funding stage, tech stack) and, above all, *who to talk to*. This page shows you how to add properties, how Pioneer fills them in, and how to get data you can act on.
## Properties turn a card into a dossier
**Properties** are custom research questions asked of every lead in a pipeline. Think of them as columns in your lead spreadsheet, except Pioneer researches the answers from the web.
**Examples:**
- LinkedIn URL
- Company headquarters
- Founding year
- Number of employees
- Technology stack
- Key contact email
Every lead also has basic built-in properties filled automatically: **Name**, **URL**, and a brief **Description**.
## Add a property
1. On your pipeline board, find the **Preferences** column, where your properties are listed
2. Click the pencil at the top of the column to open the editor
3. Add a property: name it, pick a type (text, URL, email, number, date, address, or person), and describe what you want to extract
Pioneer also suggests useful properties for your pipeline under **Recommended actions** in the Preferences column; click a suggestion to review and add it.
**Name properties for what they extract.** "Company LinkedIn URL" and "Headquarters City" are unambiguous; "contact info" makes Pioneer guess what you mean. The description is your chance to be precise, so use it.
## How enrichment fills them in
When a lead is processed, Pioneer researches each property from public web sources, extracts the value, and records what it found. Two rules matter for how you read the results:
- **If the data isn't public, it can't be extracted.** Internal metrics, unpublished emails, and private plans come back empty across the board. That's the property telling you to ask a different question.
- **An honest blank beats a confident guess.** When Pioneer can't find a trustworthy answer, the field stays empty and says so, rather than being filled with something plausible.
Enrichment happens on leads you already have, and you never pay to learn more about a lead that's already on your board.
## When the answer is a person
Some data points aren't strings; they're people. When you need to know **who** to talk to at a lead (the CEO, a founder, the head of partnerships), use a **Person property** instead of separate text properties for their name, email, and LinkedIn.
### How it works
1. Add a property and set its type to **Person** (e.g., "CEO" or "Head of Partnerships")
2. During enrichment, Pioneer identifies the actual person in that role and researches them
3. The person appears on the lead as a clickable chip with their name and photo
### The contact card
Click a person's chip to open their contact card, a mini-profile with everything Pioneer found:
- **About:** a short summary of who they are and what they focus on
- **Location:** where the person is based (city, region). Read off the LinkedIn profile card, no extra search.
- **Email:** with a verification badge: ✓ deliverable, ? uncertain (catch-all domain), ✗ likely to bounce
- **LinkedIn and X:** their actual profiles
- **Phone:** when publicly listed
- **Personal website:** their own site, portfolio, blog, or newsletter, when they have one. Always the person's *own* page, never their employer's homepage and never a directory listing.
If Pioneer looked for a channel and couldn't find it, the card says so, so you'll know the difference between "not found" and "not checked".
{/* Diagram source: /public/images/docs/contact-card-anatomy.svg (edit the SVG, re-export the PNG at 2x).
Contents: a contact card outline with five rows (About, Email with a green check badge,
LinkedIn and X, Phone, Personal website) captioned "Found, never guessed"; an arrow points to a legend of the
three email badges: green check "Verified deliverable / send with confidence", amber question
mark "Catch-all domain / worth sending, pair with LinkedIn", red cross "Likely to bounce /
run a field search instead". */}
### Grounded, never guessed
Contact details only appear when Pioneer actually found them on a real page. Emails are never pattern-guessed, and generic inboxes (info@, sales@) are never presented as a person's email. Every detail is tied to the specific person by name, so a colleague's email at the same company won't be attributed to them. Why so strict: one confidently-wrong email costs you a bounce, a burned first impression, and your trust in everything else on the card. An honest blank is the better deal.
### It keeps digging
If a person is missing details (no email yet, no LinkedIn), re-running enrichment picks up where it left off and keeps searching, filling gaps without overwriting anything already found. For one specific missing detail, you don't need a full re-run: hover the empty field on the contact card and click the **search icon** that appears (**Search?**), and Pioneer chases just that field. The same control appears on empty property values. See [Correct Pioneer's Research](/docs/guides/accuracy#missing-not-wrong).
The full person workflow (choosing your champion, reading the card, turning it into outreach) has its own guide: [Find the Right People](/docs/guides/people).
## Chain properties that build on each other
Some properties depend on others: "CEO LinkedIn" needs to know who the CEO is first; "Local Regulations" needs the headquarters city. Pioneer handles this through **property dependencies**:
1. In the property editor, look for the **Depends on** option
2. Select which property this one depends on
3. Save
Pioneer enriches parent properties first, uses their values as context for the children, and figures out the right order automatically.
**Example chain:**
```
Company Name (no dependency)
↓
Company LinkedIn URL (depends on Company Name)
↓
CEO Name (depends on Company LinkedIn URL)
↓
CEO Email (depends on CEO Name)
```
Properties at the same level run in parallel, so you don't need to think about scheduling, just about what depends on what.
(For reaching people specifically, skip the chain: a single **Person** property does the identify-and-research work in one step, with verification built in.)
Property dependency chain: Pioneer enriches in the right order
## Ask for data the web can answer
**Extract what you'll actually use.** Every property adds a column to your board and your exports. Properties "just in case" are noise you'll scroll past forever.
**Be specific.** "Contact info" is vague. "CEO Email" or "Head of Sales LinkedIn" is specific and extractable.
**Prefer public, consistent, unambiguous data.** Properties work best for information that's publicly available, consistently formatted across leads, and has one clear answer. They're weakest on private data, subjective assessments, and questions that need interpretation.
## Where property values show up
- On each lead's detail view
- On the pipeline board (properties can be shown as columns)
- In CSV exports: each property becomes a column, and person properties flatten into name, LinkedIn, email, and contact-detail columns. See [Export Your Leads](/docs/features/export).
## Next steps
- [Find the Right People](/docs/guides/people): the person-property workflow, end to end
- [Correct Pioneer's Research](/docs/guides/accuracy): fix a wrong value; chase a missing one
- [Export Your Leads](/docs/features/export): take the dossier with you
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Export Your Leads
URL: https://usepioneer.ai/docs/features/export
Pioneer's research is meant to be acted on, in your inbox, your CRM, or your outreach tool. There are two ways to take your leads with you.
## Download from the board
Click **Export** in the header of the **Leads** or **Relevant** stage. Pioneer downloads a single CSV containing every analyzed lead in the pipeline: the ones waiting in Leads, the ones you've approved, and the ones you've moved through your custom stages. Rejected leads are left out.
Each row includes:
- The lead's name and website
- The lead's relevance tier (Relevant, Mostly relevant, or Partially relevant), embedded in the TL;DR summary
- Pioneer's one-line summary of the lead
- Links back to the lead's full research in Pioneer
- One column for every [property](/docs/features/properties) in your pipeline. Properties that identify a person (like a champion or decision-maker) are split into separate columns for their name, LinkedIn, email, and other contact details.
That makes the export ready to import into a CRM or spreadsheet without cleanup: you get people and data, never internal identifiers.
Export your leads as CSV or get them via email
## The results email
When a discovery run finishes, Pioneer emails you a summary: how many leads were analyzed, your top relevant leads at a glance, and a link back to your board.
Attached to that email are two CSV files, your **relevant leads** and the leads that **weren't relevant**. The second file is worth a skim: it shows you what Pioneer is filtering out, which is exactly the feedback you need for [refining your criteria](/docs/guides/refining).
So there's no need to keep the tab open while Pioneer works. Close it, and the results will find you.
## Next steps
- [Enrich Leads with Properties](/docs/features/properties): add the data fields you want in your export
- [Refine Your Pipeline](/docs/guides/refining): improve the batch before you export it
- [From signup to your first 50 qualified leads](/docs/first-50-leads): see export in context, at the end of the full journey
- [Sharing a Pipeline](/docs/features/sharing): when a partner wants the live board, not a file
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Sharing a Pipeline
URL: https://usepioneer.ai/docs/features/sharing
By the end of this page you'll know how to give anyone (a partner, an investor, an advisor) a read-only view of a pipeline without them creating an account, whether by email or by a link you send yourself, and how to cut off that access the moment you want it gone.
## Share a pipeline in under a minute
Open the pipeline and click **Share** in the header. The **Share pipeline** dialog has a single field, and it can make two kinds of share:
- **Type your guest's email address** to send an invite. Add a short message if you like, then click **Send email invite**. Pioneer emails your guest their personal link; you never see or handle the link yourself, it goes straight to their inbox.
- **Type a name instead** ("Alex", "Board deck") and click **Create link**. Pioneer creates a personal link labeled with that name and copies it to your clipboard, so you can send it however you like: a text, a DM, a slide.
The button under the field always tells you which of the two you're about to do.
{/* SCREENSHOT: the Share pipeline dialog with the single field and the Send email invite / Create link button */}
## What your guest sees
Your guest opens their link and lands on a live, read-only view of your board: your columns, your leads, and the research behind them. (Email-invited guests type their name on first visit so your access list stays readable; guests opening a named link go straight in, since you already named that link.) Clicking any lead opens its summary, the same research document you see, minus the working controls.
Your guest also sees what the pipeline is looking for: the pipeline description, your deal-breaker and preference criteria, and the properties you track. That context is what makes the board readable to an outsider, and it usually works in your favor, because an investor who can see your qualification standards next to your leads sees the rigor behind them. If a criterion says something you'd rather keep between you and Pioneer, reword it before you share.
They can look at everything and change nothing. No drag-and-drop, no editing, no lead generation, and nothing they do can spend your credits.
{/* SCREENSHOT: the guest's read-only board view with a lead summary drawer open */}
## Why the link is personal
Each share is tied to one guest: either the email address you invited or the name you gave the link. Revoking one cuts off that one person without touching anyone else's access. That's what makes access manageable: it's a relationship between your pipeline and a specific person, not a floating URL you've lost track of.
Treat every share link like a house key. It opens the pipeline for whoever holds it, with no login step in the way. For email invites, ask your guest not to forward it; for named links, you're the one carrying the key until you hand it over, so send it directly to the person it's for. If a link ever ends up in the wrong hands, revoke it and share again: a fresh link goes out and the old one goes dead.
Share the same pipeline with as many people as you like. Each one gets their own link, and each one can be cut off independently.
## Revoke access anytime
Open the **Share** dialog again to see everyone with access: each entry shows whether it's an email invite or a personal link, when it was created, and when your guest last viewed the board. Named links keep a **Copy link** button next to them in case you need to send one again.
Click revoke next to any share and the link stops working immediately: the next time that guest opens it, the pipeline is simply no longer available. Nothing to expire, nothing to rotate.
## Next steps
- [Understanding Your Pipeline Board](/docs/pipelines): what your guest is looking at
- [Exporting Your Leads](/docs/features/export): when a partner wants the data, not the view
- [From Signup to Your First 50 Qualified Leads](/docs/first-50-leads): the full journey that fills the board you're sharing
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# My Network
URL: https://usepioneer.ai/docs/features/my-network
Your network is private to you, and it's a powerful asset. Once you bring it in, Pioneer researches each contact from the open web, building a grounded private profile. Then, on any lead where you know the person you want to reach, you can ask: *who in my network can get me in*?
## Add contacts to your network
1. Click **My Network** in the sidebar.
2. Click **Add contacts**, then paste whatever you have for the people you know:
- a **profile URL**: LinkedIn, X, or any other page someone is identifiable from (their personal site, GitHub, Substack, a faculty bio)
- an **email address**, bare (`jane@acme.com`) or named (`Jane Doe `)
One person per line, in any mix. Paste is tolerant of messy input: a clean list, a spreadsheet, a sent-mail or CRM export, or raw mixed text. Pioneer pulls the people out and ignores the leftover columns.
3. Click **Add** and Pioneer starts researching each one.
One more thing lives in the Add contacts dialog: **Show warm intro paths from my network on pipeline leads**. This is the switch that decides whether your network may appear anywhere outside My Network at all. It is off by default: a deliberate privacy choice, not an oversight. Until you turn it on, **Find warm connection** will not appear on the people on your leads. Turn it on whenever you want Pioneer to search your contacts for the way into a lead; the choice is per-user, and you can flip it back off at any time.
Pioneer works through the queue building a private profile for each contact: current role and company, a short about, recent news and posts, communities they're active in, and any contact channels it can find. Each piece of information is sourced from the page it came from.
Duplicates are dropped for you, both within the paste and against contacts you already have, including ones already synced from your calendar (matched by email address).
## Adding people by email address
An email address is enough to research someone; you don't need to find their LinkedIn first. This is what makes a sent-mail export or a CRM dump usable as-is.
An address carries two separate pieces of evidence: the **domain** says where someone works, the **mailbox** says who they are. Pioneer only accepts a person it can tie to the mailbox itself, one of:
- the name is visible in the mailbox (`jane.doe@`, `jdoe@`)
- the domain is the person's own name
- a page on the web carries that exact address next to their name
If none of those hold, research **fails** rather than guessing. That's deliberate: the wrong person in your network becomes a wrong warm path, which is worse than a blank.
**Shared mailboxes are rejected.** `info@`, `hello@`, `support@`, `careers@`, `no-reply@` and the like are a company, not a person, so Pioneer won't add them. Anything in your paste that tried to name a person but couldn't, a rejected mailbox or a link that resolves to no human, is listed back to you after adding, so you can see what was skipped and why. A paste with nobody identifiable in it is an error, never a silent "added 0".
## Research status
Each contact has a status chip:
- **Queued**: waiting to be researched. A large import may spend hours in the queue while Pioneer paces itself behind a per-user research cap.
- **Researching**: being researched right now.
- **Done**: research complete, full profile ready.
- **Failed**: couldn't be researched, or the person couldn't be pinned down with confidence. Click **Retry** to try again; an email-only contact can be retried on the address alone.
If a contact stays queued for a long time, it's not broken; the queue is working through a backlog. Only a contact that started researching and then went silent is stalled. The whole queue going quiet is the real signal that something is wrong.
## Star a contact (strong ties)
Click the star icon on any contact to mark them as a **strong tie**, someone you actually know. Starring gets them:
- **Deeper research**: a wider search of their posts, talks, and press (up to 50 signals instead of 25)
- **Guaranteed hearing**: they're seated on every ask and bridge question
- **Priority in searches**: ranked ahead of unknown contacts
Unstarring never deletes what research already found. It just removes the priority.
## The contact drawer
Click any contact to open their drawer: a researched profile with their current role, a short about, recent signals (what they posted, argued, launched, or became, with sources), and contact channels Pioneer found (email, work number, other profiles). Channels Pioneer looked for but didn't find are shown as not-found, so you know the blank is an answer, not an omission.
You can also add **private notes** to any contact: a title and a body of your own, written in Markdown. A note is your personal scratch about a relationship ("met at Battery Week, she mentioned her plant is expanding"), separate from the researched profile. Notes are private to you and never feed into research, asks, or warm paths.
## Find a warm path to a lead
If you've turned on **Show warm intro paths from my network on pipeline leads** (in the Add contacts dialog), you'll see **Find warm connection** on a lead's person card, the champion Pioneer identified on that lead. Click it, and Pioneer searches your network for people who can introduce you:
1. Pioneer writes two or three **bridge questions** ("who knows someone at this company?", "who shares a community with this person?"), each searching for a different kind of overlap.
2. Each question runs against your network and returns a shortlist of contacts who might bridge to the target.
3. The results are ranked with a confidence level, a connection type (works there, ex-colleague, same community, knows the champion, and so on), and a suggested ask: a two-line opening you can use.
You can also type your own bridging question if the generated ones miss. Every person named is a link into their contact drawer.
**What if nobody is a match?** Zero is a legitimate result. Pioneer shows you the closest near-misses and why each was passed over, so you learn what your network has instead of what you asked for.
## Ask your network a question
Beyond warm paths on specific leads, you can ask a plain-language question of your whole network: *"Who should I talk to about process-heat incentives in California?"* or *"Who in my network knows the founders at Acme?"*
1. Go to **My Network** and click **Ask your network**.
2. Type your question. Pioneer reads every researched contact and returns a handful of grounded suggestions: who, why them (citing what they actually did recently, not just their title), and a suggested opening.
3. Results appear as a short list. Each contact is a link into their drawer; each suggestion cites the evidence.
One ask at a time per user. If a previous ask is still running, you'll need to wait or cancel it.
**What if nobody is a match?** Zero is a legitimate result. Pioneer shows you the closest near-misses and why each was passed over, so you learn what your network has instead of what you asked for.
## Share a link to your network
You can create a shareable link that lets someone else, even someone without a Pioneer account, ask a question against your network. This is useful when the person who needs the intro is a co-founder, an advisor, or a friend who wouldn't sign up for Pioneer themselves.
### Create a share link
1. Go to **My Network** and click **Share**.
2. Choose how many questions the link may ask (1, 2, 5, 10, or 50). That allowance is what keeps one shared link from spending your whole network-ask budget.
3. Optionally label the link (like "Co-founder" or "Sequoia intro") so you can keep track of who you shared it with, and optionally tick **Only one email address can use this link** and type that address.
4. Click **Create share link**. The URL lands on your clipboard, ready to send.
You need at least one contact in your network before you can share it.
### How it works for the person you shared it with
They open the link and see whose network it is, how many contacts it holds, and an ask box. Before asking, they verify an email address with a 6-digit code Pioneer sends them, so you always know who asked; if you restricted the link to one address, that's the only address that works. Then they type a question, and Pioneer answers with grounded suggestions from **your** network: who, why them, and a suggested opening. They never see your contact list, and they never need a Pioneer account.
### Manage your links
Open the same **Share** dialog to see every link you've made: its label, whether it's still active, how many of its questions are used up, and every question asked through it with the answer it got. **Copy** grabs the URL again. **Revoke** ends a link at once, for everyone holding it: anyone who opens it afterwards sees "This link is no longer available". Revoking keeps the question history, which is your record of what was asked.
Share links are read-only. The person using one can ask questions and read the answers; they can never see, edit, or export your network.
## Manage your network
Your network is private to you: never shared with teammates, never mixed into the org's shared records. Contacts you add, research Pioneer runs, warm paths you find, and asks you make are yours alone.
To remove a contact, go to My Network, open the contact's drawer, and click **Remove**. This deletes the contact and all their research.
To add a private note to a contact, open the contact's drawer and click **Add note** in the **Notes** section. Give the note a title (leave it blank and it gets a dated one) and a body; you can edit or delete a note at any time.
## Next steps
- [Refine Your Pipeline](/docs/guides/refining): get more signal from every batch
- [Export Your Board](/docs/features/export): take your leads into your outreach workflow
- [Troubleshooting & FAQ](/docs/troubleshooting): answers to common questions
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Refine Your Pipeline
URL: https://usepioneer.ai/docs/guides/refining
## Why refinement matters
Your first batch of leads is a starting point, not a verdict. Pioneer works like a new team member: it gets dramatically better once you tell it what you actually meant. Teams that spend five minutes refining after each batch consistently end up with pipelines where most leads are worth pursuing. Teams that never refine end up filtering by hand, which is the work Pioneer should be doing for you.
## The refinement loop
The loop is short and worth internalizing:
1. **Review** a batch of leads: approve the good ones, reject the bad ones
2. **Notice the pattern:** what do the bad ones have in common? What's missing from the good ones?
3. **Refine:** turn that pattern into a criteria change
4. **Repeat:** ask Pioneer for more leads and compare the new batch to the last one
Each pass through the loop should feel noticeably better. If two consecutive batches don't improve, change your approach (see "Common situations" below).
The refinement loop: review, notice the pattern, refine, repeat
## Your board moves teach on their own
Steering and criteria edits are explicit instructions. There's also a second feedback channel that runs without any extra work from you: the board itself.
When you ask Pioneer for more leads, the new discovery run first reads what happened to the previous ones: which leads you kept and how far they've moved through your stages, and which ones you rejected straight out of Leads, along with the deal-breaker each one failed. It uses that record to choose better search strategies: more like the leads you advanced, and none of whatever produced the ones you rejected on sight.
Two practical consequences:
- **Reject the obvious misses before asking for more leads.** A rejection out of the Leads column is the clearest "stop finding these" signal you can send, far stronger than leaving bad leads sitting unreviewed. An unreviewed board teaches nothing.
- **Your column names are part of the signal.** Pioneer reads how far leads have travelled using your own stage names, so a board with meaningful stages ("Scheduling", "Sent proposal") teaches more than one where everything piles up in Relevant.
One reassurance: rejecting a lead from a *later* stage doesn't count against discovery. A lead that reached Scheduling and then fell through was still a good find; only rejections straight out of Leads are read as "you found the wrong company." So work your pipeline honestly; the learning sorts itself out.
## Your refinement tools
Everything lives in the **Preferences** column on the left of [your board](/docs/pipelines).
### Recommended actions
Pioneer analyzes your pipeline (your criteria, your properties, and how your leads are scoring) and suggests up to three concrete improvements. Each suggestion is a specific change: tighten a criterion, add a missing one, or add a property worth extracting.
- Click a suggestion to see the exact change before it's applied; nothing changes without your review
- Hit the refresh icon next to "Recommended actions" to generate a fresh set
Recommended actions are the fastest way to refine when you're not sure what to change.
### Steering
The text box at the bottom of the Preferences column takes plain-language instructions:
- "More hardware companies, fewer software resellers"
- "Exclude consulting firms and agencies"
- "Focus on companies that have raised money in the last year"
- "These are too big, I want companies under 100 people"
Pioneer turns your instruction into a concrete criteria change and shows it to you for review. Steering is the right tool when you know what's wrong but don't want to hand-edit criteria.
### Direct editing
Click the pencil at the top of the Preferences column to open the editor and change your description, criteria, or properties yourself. Best when you know exactly what you want.
## Reading your results
Refinement works better when you understand what the board is telling you:
**Your criteria are descriptions, not filters.** Pioneer researches each lead and judges, criterion by criterion, how strongly *that* lead matches what you described. Refinement is therefore a conversation about intent: you sharpen the description, and Pioneer's judgment of every lead sharpens with it.
**The relevance rule is mechanical.** A lead is **relevant** when it meets *every* MUST criterion, **mostly relevant** when it meets most of what matters, and **partially relevant** otherwise. SHOULD criteria never make or break the relevance tier.
**The order within the column is a different signal.** A lead's position comes from adding up how strongly it matched each of your criteria, with a met MUST weighing substantially more than a SHOULD, which is what keeps relevant leads above the rest. Because those strengths are judged per lead, position tells you something the verdict doesn't: a relevant lead sitting near the bottom cleared your rules only weakly, and is usually the most informative lead in the batch to open. Full mechanics: [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria).
**Open the criteria breakdown before overriding it.** When a lead you like isn't relevant, click into it and find which MUST criterion failed and what evidence Pioneer cited. Two very different conclusions follow:
- *Pioneer was right:* the lead genuinely fails your rule. Your criteria are working.
- *Your criterion is wrong:* the rule is stricter than what you actually believe. Fix the criterion, not the lead.
**Watch for "Inconclusive."** Inconclusive means Pioneer couldn't find enough public evidence either way. On a SHOULD that's an honest "don't know" and it doesn't drag the ranking down, but on a MUST it counts as not met and disqualifies the lead, because a MUST passes only on affirmative evidence. If one criterion is inconclusive across many leads, it's either not discoverable from public information or phrased so that nothing could confirm it, so rewrite it around something the web can actually answer. See [Write rules that can be confirmed, not just contradicted](/docs/concepts/criteria#write-rules-that-can-be-confirmed-not-just-contradicted).
## Common situations
**Too much noise (most leads are barely relevant)**
Your criteria are too loose, or too vague to judge a lead against. Promote your most important SHOULD to a MUST, or steer: "Be stricter, only companies that clearly [your key requirement]."
**Too narrow (barely any leads arrive)**
Your MUSTs are doing too much work. Demote borderline MUSTs to SHOULD, or broaden the description. It's better to review a slightly wider set than to starve the pipeline.
**Right industry, wrong companies**
The description matches but the details are off: wrong size, wrong stage, wrong geography. Steer with the specific correction: "Right space, but I need earlier-stage companies."
**Good leads, weak information**
Recommendations are fine but you're missing the data you need to act. That's a properties problem, not a criteria problem: add the fields you need (see [Enrich Leads with Properties](/docs/features/properties)).
## A worked example
Say you're selling compliance software and start with: *"B2B fintech companies in the US."*
**Batch 1:** Lots of leads, but half are tiny two-person startups. You reject them and steer: *"Exclude pre-product startups, I want companies with a live product and real customers."* Pioneer proposes a new MUST criterion; you accept it.
**Batch 2:** Better. But several leads are payment processors, regulated differently, not your buyer. You add a MUST directly: *"Must handle consumer financial data (lending, banking, or personal finance products)."*
**Batch 3:** Strong matches, but you notice the best ones all have compliance job postings. You promote that from an observation to a SHOULD: *"Should have open compliance or risk roles."* Companies with a live posting now match that rule strongly and climb; companies with only a stale mention of compliance match it weakly and settle below them, which is exactly the ordering you wanted.
Three short passes, maybe ten minutes total, and the pipeline went from "broad list" to "ranked list of companies that need exactly what you sell."
## What happens when criteria change
When your criteria change, Pioneer re-checks your existing leads against the updated rules and uses the new criteria for everything it discovers next. You don't need to restart anything; refinement applies to the whole pipeline.
## Next steps
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): the full guide to writing criteria
- [Pipeline Best Practices](/docs/guides/quality): quality vs. quantity tradeoffs
- [From signup to your first 50 qualified leads](/docs/first-50-leads): the refinement loop inside the full journey
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Find the Right People
URL: https://usepioneer.ai/docs/guides/people
## From companies to conversations
Qualifying a company tells you *where* to sell. It doesn't tell you *who* to talk to. The gap between those two is where most BD time disappears: hunting through LinkedIn, guessing email formats, emailing info@ and hoping.
Pioneer closes that gap with **Person properties**: you name the role you need, and Pioneer identifies the actual human in that role at each lead, researches them, and returns verified ways to reach them. By the end of this page, every recommended company on your board comes with a person, a channel, and a reason to write.
{/* Diagram source: /public/images/docs/people-flow.svg (edit the SVG, re-export the PNG at 2x).
Contents: left-to-right flow of five nodes: "Qualified company (on your board)" →
"Person property (\"VP Engineering\")" → "Pioneer researches (the actual human)" →
"Contact card (verified channels)" (highlighted in Pioneer blue) →
"Personalized outreach (evidence you can cite)". */}
## When the lead itself is a person
Not every pipeline chases companies. If your target is a person (a consultant to hire, a podcast guest, an investor, a speaker), add them the same way you'd add a company (by name, email, or profile link), and Pioneer researches the person themselves. The lead's card becomes their own mini-dossier: a short about, recent activity, and an email with the same verification badge described in Step 3: never a guessed address, never a generic inbox. The research-quality rules don't change just because the lead has one employee.
## Step 1: Decide who your champion is
Before adding properties, get specific about the role that says yes to you:
- Selling a developer tool? Your champion is probably a **VP of Engineering** or **CTO**, not the CEO.
- Selling to finance teams? **Controller** or **VP Finance**.
- Early-stage targets? At small companies, go straight for a **founder**.
One well-chosen role beats three vague ones. You can always add a second Person property later (say, an executive sponsor alongside your hands-on champion).
## Step 2: Add a Person property
1. On your pipeline board, open the **Preferences** column and click the pencil to edit
2. Add a property and set its type to **Person**
3. Name it for the role: "CEO", "Head of Partnerships", "VP Engineering"
That's the whole setup. As leads are enriched, Pioneer identifies the actual person in that role at each company and researches them. Each found person appears on the lead as a clickable chip with their name and photo.
**Tip:** name roles the way the market names them. "Head of Partnerships" finds people; "the person who handles partnerships" makes Pioneer guess what you mean.
From a qualified company to the right person with verified contact details
## Step 3: Read the contact card
Click a person's chip to open their contact card:
- **About:** a short summary of who they are and what they focus on. Read this first: it's your personalization material.
- **Location:** where the person is based (city, region). Read off the LinkedIn profile card Pioneer already fetches, no extra search. Helps you know if they're in your timezone or reachable for an in-person meeting.
- **Email:** with a verification badge that tells you whether the address will bounce *before* you send. Four states: **Email verified** (the mailbox exists); **Email catch-all** (the company's server accepts every address, so this specific mailbox can't be confirmed); **Email invalid** (verification failed, this address will bounce); **Email not verified** (nothing has confirmed this mailbox exists yet, so treat it like a missing email until a check earns it a verdict). A gray "not verified" badge also appears while no check has been made at all, since an unconfirmed address must never look like a confirmed one. Pioneer finds the email from the company's public website, the person's LinkedIn profile, or other public sources, never from guessing or pattern construction.
- **LinkedIn and X:** their actual profiles
- **Phone:** when publicly listed
- **Personal website:** their own site, portfolio, blog, or newsletter, when they have one. Always the person's *own* page, never their employer's homepage and never a directory listing.
If Pioneer looked for a channel and couldn't find it, the card says so, so you'll always know the difference between "not found" and "not checked".
### Why you can trust it
Every detail on the card is **found, never guessed**:
- Emails are never pattern-guessed from name@company.com conventions
- Generic inboxes (info@, sales@) are never presented as a person's email
- Every detail is tied to the specific person by name, so a colleague's email at the same company won't be attributed to them
This is the difference between a contact card and a contact *database row*: when Pioneer shows you an email with a ✓, someone real is on the other end of it.
## Step 4: Fill the gaps
People research is incremental, and you can aim it.
**Missing one detail?** Hover over the empty field on the person's contact card, say, an email that came back not found, and a small search icon appears. Click it and confirm **Search?**, and Pioneer runs another research pass focused on that one field. Nothing already found is touched; the pass just chases the missing detail harder. The same control appears on empty property values on a lead. It's free: you never pay to learn more about a lead you already have. The confirm is there so a stray click doesn't kick off a research pass you didn't mean to start.
**Missing a lot?** Re-running enrichment on the lead picks up where research left off and keeps searching everything. It fills gaps without overwriting anything already found, so there's no risk in running it again.
A practical rhythm: review your newly qualified leads, approve the good ones, then re-run enrichment on the approved set so your best leads get the most complete contact data, and use the field-level search when one missing email is all that stands between you and an otherwise-perfect contact.
## Step 5: Turn the card into outreach
The contact card gives you the two things cold outreach needs:
1. **A real channel:** an email marked ✓, or a LinkedIn profile as fallback
2. **A reason to write:** the About summary plus the lead's qualification evidence
A workable pattern: open the lead's summary and [criteria results](/docs/concepts/leads), take the single most specific fact Pioneer found (a recent announcement, a hiring push, a stated priority), and lead your message with it. You already have the research, so use it in the first sentence, not the fourth paragraph.
Before you write cold, check whether you have to. On the person card, **Find warm connection** searches your own contacts for someone who can introduce you; see [My Network](/docs/features/my-network).
## Person properties vs. text properties
Don't build people out of text fields. A "CEO Name" text property plus a "CEO Email" text property gives you two disconnected strings: no verification, no grounding, no profile links, no gap-filling.
One **Person** property gives you the researched human with all of it attached. Use text properties for facts about the *company* (headquarters, funding stage); use Person properties for humans.
## Next steps
- [Enrich Leads with Properties](/docs/features/properties): the full properties reference, including dependencies
- [My Network](/docs/features/my-network): find a warm path to the person instead of writing cold
- [Correct Pioneer's Research](/docs/guides/accuracy): when a detail is wrong, flag it once and it never comes back
- [Refine Your Pipeline](/docs/guides/refining): better companies in means better people out
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Correct Pioneer's Research
URL: https://usepioneer.ai/docs/guides/accuracy
## When Pioneer gets something wrong
Pioneer researches the open web, and the open web is messy. Two people share a name, a company has a lookalike, an old profile photo lingers on a directory site. Most of what Pioneer finds is right, but when something isn't, you shouldn't have to live with it or fix it by hand.
Every researched value on a lead can be flagged as wrong, directly where you see it. By the end of this page you'll know both tools: the fix for a *wrong* value and the targeted search for a *missing* one.
## Marking a value inaccurate
1. Hover over the value, and a small trash icon appears next to it
2. Click it, then confirm **Redo?**
3. That's it
Three things happen the moment you confirm:
- **The wrong value is cleared.** It disappears from the lead immediately.
- **Pioneer remembers what you rejected.** That exact value is blocked for this lead, permanently. Re-research will never bring it back.
- **A targeted re-research starts.** Pioneer goes looking for a correct replacement for just that field, not the whole lead.
You'll see the field fill back in when the re-research finishes. If Pioneer can't find a trustworthy replacement, the field stays empty: an honest blank beats a confident mistake.
Wrong value vs. missing value: two different tools
## What you can mark
**Person details**, every researched field on a person:
- Photo
- Email address
- Phone number
- LinkedIn profile
- X (Twitter) profile
- Personal website
- About / bio
- Recent news
**Property values**, any custom [property](/docs/features/properties) Pioneer extracted (deal size, tech stack, funding stage, whatever you've defined). Marking a property value inaccurate works the same way: the value clears, the rejection is remembered, and Pioneer re-researches that property with the wrong answer excluded.
## Missing, not wrong?
Marking is for values Pioneer got *wrong*. When a value is simply *missing*, a field that came back not found, there's a lighter tool: hover over the empty field and a small **search icon** appears. Click it and confirm **Search?**, and Pioneer runs another research pass that chases just that field, without clearing or redoing anything else on the lead. It works on person fields and property values alike.
In short: wrong value → trash icon (clears it, blocks it from returning, re-researches). Missing value → search icon (just searches harder).
## Why this beats editing by hand
You *can* just note the correct value elsewhere and move on, but marking teaches Pioneer something durable:
- **The mistake can't recur.** Re-enriching the lead later (or refreshing properties) will never re-store a rejected value. Hand-corrections don't have that guarantee: the next research pass could overwrite them.
- **The replacement is researched, not guessed.** Pioneer re-verifies from sources, so the new value comes with the same evidence trail as everything else on the lead.
- **It compounds.** Rejections make Pioneer more careful about the same trap. For example, an email at a different company's domain won't be attached to your lead's contact again.
## Common cases
**Wrong email.** The classic case is a same-named person at a different company. Mark it: the address is blocked for this lead and Pioneer re-searches with the company context enforced. Email verification badges (✓ / ? / ✗) tell you about deliverability, but only you can spot "right person, wrong company", which is exactly what marking is for.
**Wrong photo.** Profile photos come from public sources and occasionally match the wrong person. Mark it and a corrected photo is re-targeted specifically.
**Wrong social profile.** A LinkedIn or X link pointing at a namesake. Mark it; the bad URL can't return.
**Stale or wrong property value.** A "team size" from an old article, a mis-read funding stage. Mark the value rather than ignoring it: your board sorts and filters on properties, so one wrong value can hide a good lead.
## What marking is *not* for
- **A lead that's entirely the wrong company or person.** Reject the lead itself from the board instead; that's feedback on targeting, not on one field.
- **A value that's correct but unwanted.** If the data is right but the criterion or property is wrong, edit those in the **Preferences** column. See [Refine Your Pipeline](/docs/guides/refining).
## Next steps
- [Find the Right People](/docs/guides/people): how person research works
- [Refine Your Pipeline](/docs/guides/refining): teaching Pioneer at the targeting level
- [Troubleshooting & FAQ](/docs/troubleshooting): quick answers to common issues
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Pipeline Best Practices
URL: https://usepioneer.ai/docs/guides/quality
This page collects the judgment calls that don't fit a single feature: how tight to make your criteria, when to cast wide, and how to keep a pipeline healthy over weeks of use. Read it after your first batch or two, since the advice lands better once you've seen real results.
## Set up for success
### Start with your purpose
Your stated purpose powers Pioneer's recipe suggestions, so a clear purpose pays for itself before you've built anything.
**Vague:** "Sales stuff"
**Clear:** "Finding enterprise customers in financial services for our compliance automation platform"
### Use recipes as starting points
Recipes aren't final; they're starting points. Click **Try this** to pre-fill a pipeline, then:
- Adjust the description to be more specific
- Modify criteria based on what you know about your market
- Add or remove criteria as needed
### Don't over-engineer upfront
Start with 3–5 criteria, let Pioneer find a batch, and adjust based on what arrives. Iterating against real results is faster than theorizing, and Pioneer's refinement tools are built for exactly that loop. The loop itself: [Refine Your Pipeline](/docs/guides/refining).
## Choose your quality/quantity tradeoff deliberately
### When to cast a wide net
**Broad criteria make sense when:**
- You're exploring a new market
- Your targets are abundant
- You have time to review and filter
**How to do it:** more SHOULD criteria, fewer MUST; general descriptions; accept that you'll reject many leads, because rejections are cheap and they teach.
### When to focus on quality
**Tight criteria make sense when:**
- Your time is limited
- Your targets are specific
- False positives are costly (bad outreach hurts reputation)
**How to do it:** more MUST criteria, specific and verifiable; accept that you might miss edge cases.
### The 70% rule
A good heuristic: if roughly 70% of your leads are worth pursuing, your criteria are well-tuned.
- Much higher (90%+)? You might be too restrictive: strong matches are being filtered out before you see them.
- Much lower (50%-)? You're wasting time on noise. Tighten criteria.
The 70% sweet spot: well-tuned criteria means most leads are worth pursuing
## Use MUST and SHOULD strategically
**MUST criteria are gates:**
- "Must have raised Series A": no seed companies at all
- "Must be B2B": no consumer companies
**SHOULD criteria are preferences:**
- "Should have 50+ employees": prefer larger, but consider smaller
- "Should be in the US": prefer domestic, but consider international
**Strategy:** start with MUST for absolute deal-breakers only, SHOULD for everything else. If results are too noisy, promote your most important preference to a MUST, one promotion at a time, so you can see what each change does. The mechanics behind the tiers: [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria).
## Keep the board working for you
### Process the Leads column regularly
Don't let leads pile up:
1. Quick scan for obvious strong matches → approve them
2. Quick scan for obvious non-matches → reject them
3. Deeper review for the uncertain ones
### Make custom stages match your real workflow
**Sales workflow:** Relevant → Researching → Contacted → Meeting → Proposal → Done
**Partnership workflow:** Relevant → Evaluating → Reached Out → In Discussion → Done
Stages you actually move leads through beat aspirational ones you'll ignore.
### Reject aggressively
Rejected leads aren't deleted; rejecting the barely relevant matches keeps your Leads column focused, and your rejections teach the next discovery run what to stop finding: Pioneer reads which leads you rejected on sight, and the deal-breaker each one failed, before it searches again. A board where everything is "maybe" teaches nothing.
## Get more from properties
**Only extract what you'll use.** Every property adds a column to your board and exports. Add fields for your workflow, not "just in case."
**Use Person properties for people.** Need to reach the CEO, a founder, or the head of partnerships? Don't build separate text properties for their name, email, and LinkedIn. Add a single **Person property** and get the researched human with verified contact details. See [Find the Right People](/docs/guides/people).
**Use dependencies for data that builds on data.** For non-person data, chains help when one property needs another as context:
1. Company Name
2. Headquarters City (depends on Company Name)
3. Local Incentive Programs (depends on Headquarters City)
Details: [Enrich Leads with Properties](/docs/features/properties).
## Avoid the common mistakes
**Too many criteria** restricts results toward zero. Start simple, add criteria as needed.
**Too-vague descriptions:** "Find good companies" gives Pioneer nothing to aim at. Specificity compounds: "B2B SaaS" → "B2B SaaS building developer tools" → "B2B SaaS building API observability tools".
**Ignoring results:** if results aren't what you expected, the fix is a refinement pass, not patience. Pioneer follows your words; make the words match your intent.
**Not rejecting:** hundreds of unprocessed leads make a pipeline unwieldy and starve the feedback loop.
## Next steps
- [Refine Your Pipeline](/docs/guides/refining): the loop these practices feed into
- [Example Pipelines](/docs/guides/use-cases): full setups for six common goals
- [Enrich Leads with Properties](/docs/features/properties): the data side of a great pipeline
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Example Pipelines
URL: https://usepioneer.ai/docs/guides/use-cases
Pioneer works for any web-research goal. Below are six complete setups you can adapt: copy the description, tune the [criteria](/docs/concepts/criteria) to your market, and add the [properties](/docs/features/properties) you'll actually use. Treat each as a starting point; your first [refinement pass](/docs/guides/refining) will fit it to your exact taste.
Six core use cases for Pioneer
## Finding customers
The classic use case: discovering companies or people who might buy your product.
### Example: Enterprise SaaS sales
**Description:** "Series B+ B2B SaaS companies in the HR tech space with 100+ employees and a presence in North America"
**Criteria:**
```
MUST:
- Must be a B2B company (not selling to consumers)
- Must be a software/SaaS company
- Must have raised Series B or later funding
SHOULD:
- Should have 100+ employees
- Should have a presence in the United States
- Should operate in HR tech, people ops, or workforce management
- Should have a dedicated sales or partnerships team
```
**Properties to add:**
- Company LinkedIn URL
- Headquarters location
- Head of [relevant department], as a **Person property**, so you get the human with verified contact details, not just a name
## Finding investors
Founders can use Pioneer to discover investors who fit their profile.
### Example: Seed investor discovery
**Description:** "Active seed-stage investors who invest in B2B SaaS, particularly in the developer tools or infrastructure space"
**Criteria:**
```
MUST:
- Must be an active investor (investments in the last 2 years)
- Must invest at seed or pre-seed stage
- Must invest in B2B software
SHOULD:
- Should have invested in developer tools or infrastructure
- Should be based in SF Bay Area or NYC
- Should lead rounds (not just participate)
- Should have a thesis or focus area that includes our space
```
**Properties to add:**
- Investor LinkedIn
- Fund name
- Portfolio company examples
- Investment thesis URL
## Finding partners
Integration partners, channel partners, co-marketing: Pioneer can find them.
### Example: Integration partnerships
**Description:** "B2B software companies that serve a similar customer profile and have active integration or partnership programs"
**Criteria:**
```
MUST:
- Must be a B2B software company
- Must serve overlapping customer segments
- Must NOT be a direct competitor
SHOULD:
- Should have an active integrations/partner page
- Should have existing integrations with common tools (Slack, Salesforce, etc.)
- Should have partnership application or contact info visible
- Should have a technical team (can implement integrations)
```
**Properties to add:**
- Partnerships page URL
- Partnership contact, as a **Person property**
- Existing integration count
- Technology stack
## Finding vendors
Evaluating service providers, agencies, or SaaS tools for your own use.
### Example: Design agency evaluation
**Description:** "Design agencies that specialize in enterprise B2B software products and have experience with complex UX challenges"
**Criteria:**
```
MUST:
- Must be a design agency or consultancy
- Must have B2B software in their portfolio
- Must have a team (not a solo freelancer)
SHOULD:
- Should have enterprise clients in portfolio
- Should specialize in product design (not marketing)
- Should have case studies with measurable outcomes
- Should be based in the US or have US working hours
```
**Properties to add:**
- Portfolio URL
- Notable clients
- Team size
- Primary service offerings
## Competitive intelligence
Understand your market by discovering companies in your space.
### Example: Competitive landscape mapping
**Description:** "Companies building [similar product category] for [target market], including both direct competitors and adjacent players"
**Criteria:**
```
MUST:
- Must offer a product in [category]
- Must serve [target market]
SHOULD:
- Should have raised funding (indicates traction)
- Should have launched publicly
- Should have customer testimonials or case studies
- Should have press coverage or industry recognition
```
**Properties to add:**
- Funding amount/stage
- Launch date
- Key differentiators (from website messaging)
- Pricing model
## Talent sourcing
Finding people with specific skills or backgrounds.
### Example: Technical leadership candidates
**Description:** "Engineering leaders (VP/Director level) at Series A-C startups who have scaled teams from 10 to 50+ engineers"
**Criteria:**
```
MUST:
- Must be VP Engineering, Director of Engineering, or equivalent
- Must have experience at venture-backed startups
- Must have scaled engineering teams
SHOULD:
- Should have been at current role for 2+ years
- Should have B2B software experience
- Should be based in [target geography]
- Should have visible thought leadership (blog, talks, etc.)
```
**Properties to add:**
- LinkedIn URL
- Current company
- Years in current role
- Previous companies
## Research and analysis
Any systematic web research task works in Pioneer.
### Example: Industry report research
**Description:** "Climate tech startups working on carbon removal, capture, or sequestration technologies"
**Criteria:**
```
MUST:
- Must be working on carbon removal/capture
- Must be a company or startup (not a research project)
SHOULD:
- Should have raised funding
- Should have a working prototype or deployed technology
- Should have published technical details or papers
- Should be actively hiring
```
**Properties to add:**
- Technology type
- Funding stage
- Key technology claims
- Team size
## Next steps
- [Create Your First Pipeline](/docs/first-pipeline): turn one of these into a running pipeline
- [Teach Pioneer What a Great Lead Looks Like](/docs/concepts/criteria): adapt the criteria to your market
- [Refine Your Pipeline](/docs/guides/refining): fit the setup to your taste after the first batch
## Need help?
If you have questions or want help setting up a pipeline for your specific use case, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Outbound
URL: https://usepioneer.ai/docs/outbound
Outbound fails for two reasons: you're writing to the wrong companies, or you're writing cold to the right ones. Pioneer works on both. It researches the open web for companies that match what you actually sell, finds the person who owns the problem, and then checks your own network for someone who can introduce you to them.
## Describe who should be buying from you
A [pipeline](/docs/pipelines) starts with a plain-language description. Write it the way you'd brief a new rep, not the way you'd fill in a database filter:
> Companies installing industrial process heat in North America that have publicly committed to cutting Scope 1 emissions, 200–5,000 employees, and are already spending on electrification consultants.
Then set [criteria](/docs/concepts/criteria). MUST rules are your deal-breakers, and a lead is **relevant** only when every one of them passes:
- MUST operate industrial sites in the US or Canada
- MUST have a published decarbonization commitment
- MUST NOT already run an in-house electrification team
- SHOULD have announced capex on plant upgrades in the last 18 months
- SHOULD be in food & beverage, chemicals, or pulp & paper
The SHOULD rules don't exclude anyone; they rank. That's what makes the top of your board worth working first.
## Add the fields your sequence needs
[Properties](/docs/features/properties) are the columns you'd otherwise fill in by hand before writing a single email: current supplier, plant count, the name of the sustainability lead, the last relevant announcement and its date. Pioneer researches each one per lead and cites where the answer came from, so an [export](/docs/features/export) drops into your sequencing tool already populated.
Only add properties you'll actually use in the message. Every extra column is research spend and one more thing to sanity-check.
## Get the person, not just the company
A company isn't reachable; a person is. [Find the Right People](/docs/guides/people) locates the actual human in the role you care about, with contact details that were **found and sourced, never guessed**. If Pioneer can't confirm an address, it says so rather than inventing a `firstname.lastname@` pattern that bounces and burns your domain.
## Then don't send it cold
Bring the people you know into [My Network](/docs/features/my-network), pasting LinkedIn URLs, a sent-mail export, or a CRM dump, and Pioneer researches each contact into a private profile. On any lead's person card, click **Find warm connection** and Pioneer searches your network for a path to them: who bridges to this company or person, what the overlap is (ex-colleague, works there, same community, knows them directly), and a two-line ask you can send to the bridge.
If nobody in your network reaches them, Pioneer tells you that and shows the near-misses it rejected. A clear zero is worth more than a weak "maybe try this person".
## Work the board, and let it learn
Approving and rejecting leads is not bookkeeping; it's the training signal. Every judgment you record teaches the pipeline your taste, and the next batch is better for it. Fifteen minutes of [refinement](/docs/guides/refining) after a batch is the highest-return habit in the product; getting a researched value corrected takes one click on [mark inaccurate](/docs/guides/accuracy).
## Hand the whole loop to your agent
Everything above is available to whatever AI agent you already use (Claude Code, Codex, ChatGPT, OpenClaw, or your own) through the [API](/docs/api). A common setup: the agent creates the pipeline from your brief, checks each morning for newly researched leads, pulls the warm paths, and drafts the intro requests for you to send. See [Use Pioneer With Your Agent](/docs/agents).
## Next steps
- [Create Your First Pipeline](/docs/first-pipeline)
- [Find the Right People](/docs/guides/people)
- [My Network](/docs/features/my-network)
- [Partnerships](/docs/partnerships) and [Fundraising](/docs/fundraising): the same machine, pointed elsewhere
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Partnerships
URL: https://usepioneer.ai/docs/partnerships
Partnerships are a relationship business before they're a pipeline business. A cold note to `partners@` almost never lands, and the companies worth partnering with are rarely the ones ranked highest by size. Pioneer helps you find the ones whose customers and product line up with yours, then finds the person you both know.
## Describe the overlap, not the company size
Write the [pipeline](/docs/pipelines) description around the reason a partnership would work:
> Software companies selling into commercial building owners in Europe whose product sits next to ours in the same buying process, 20–500 employees, with an existing integrations or marketplace program.
The strongest partnership signals are on the open web and no database filters on them, which is exactly what [discovery](/docs/concepts/discovery) is for: a public partner directory, a joint webinar, a marketplace listing, a shared customer logo, a job posting for a partnerships hire.
## Criteria that separate a real partner from a lookalike
- MUST sell to the same buyer we do (building owners / facilities)
- MUST NOT compete with our core product
- MUST have a public integrations or partner page
- SHOULD have a named partnerships owner
- SHOULD share at least one customer with us
- SHOULD have shipped a new integration in the last year
That MUST NOT rule is the one that saves the most time: competitor lookalikes dominate any keyword search for partners and Pioneer will drop them for you, with the reasoning shown on the card.
## Useful properties for partner evaluation
[Properties](/docs/features/properties) to research per candidate:
- partner or marketplace page URL
- existing integrations (and whether any is with a competitor of ours)
- overlapping customers we can name
- partnerships owner: name, title, and where they said something about partnering
- co-marketing footprint: webinars, joint case studies, conference booths
Each value cites its source, so when you take a shortlist to your team you're arguing from evidence rather than from a hunch.
## Reach the partnerships owner warmly
This is where partnerships differ most from outbound: the intro path matters more than the message. Bring your contacts into [My Network](/docs/features/my-network), then use **Find warm connection** on the person card of any partner candidate. Pioneer writes bridge questions ("who has worked at this company?", "who shares a community with this person?"), runs them against your researched contacts, and returns ranked paths with a suggested ask.
You can also skip the lead entirely and [ask your network](/docs/features/my-network#ask-your-network-a-question) in plain language: *"Who do I know who has partnered with an HVAC software vendor?"*
And when the person best placed to make the intro isn't you (a co-founder, an investor, an advisor), [share a link to your network](/docs/features/my-network#share-a-link-to-your-network) so they can ask a question against it without a Pioneer account and without ever seeing your contact list.
## Keep the board as your partner CRM-lite
Statuses and buckets on the board track where each conversation stands; [sharing a pipeline](/docs/features/sharing) gives a read-only link to whoever needs visibility. [Notes](/docs/features/my-network#add-contacts-to-your-network) on a contact are the right place for the private relationship detail ("met at Battery Week, they're rebuilding their marketplace in Q3").
## Hand it to your agent
Your agent can run this loop for you through the [API](/docs/api): maintain the partner pipeline, watch for new marketplace and integration announcements, and surface which new candidates already have a warm path. See [Use Pioneer With Your Agent](/docs/agents).
## Next steps
- [Set Your Criteria](/docs/concepts/criteria)
- [My Network](/docs/features/my-network)
- [Outbound](/docs/outbound) and [Fundraising](/docs/fundraising)
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Fundraising
URL: https://usepioneer.ai/docs/fundraising
An investor list is easy to get and almost worthless. What decides a raise is whether the fund actually invests at your stage in your sector right now, whether you reach the *partner* who owns that thesis, and whether you get in warm. Pioneer researches all three.
## Describe the fund you want, not "VCs"
Write the [pipeline](/docs/pipelines) description like the sentence you'd say to a friend who offers to help:
> Funds writing $2–8M Series A checks into industrial decarbonization or energy hardware in Europe or the US, that have led at least two rounds in the last 18 months and have a partner who has written publicly about process heat.
## Criteria that keep the list honest
- MUST have led a round at our stage in the last 18 months
- MUST invest in hardware or industrial technology
- MUST NOT hold a position in a direct competitor
- SHOULD have a named partner with a public thesis in our space
- SHOULD have participated in a follow-on round with a portfolio company
- SHOULD have offices or active deals in our geography
The competitor MUST NOT rule and the "still active at our stage" rule are the two that remove most of the noise from any public investor list, and Pioneer shows the evidence for each verdict on the [lead card](/docs/concepts/leads), so a "no" is auditable.
## Research the partner, not just the fund
Useful [properties](/docs/features/properties) per fund:
- check size and stage, with the announcement it came from
- most recent lead investment (name and date)
- relevant portfolio companies, and any that are competitive with us
- the partner who owns this thesis, with what they wrote or said and where
- whether they follow on
Then use [Find the Right People](/docs/guides/people) to get the individual partner rather than a general `info@` inbox. Contact details are found and sourced, never guessed.
## Get introduced instead of applying
Cold inbound is the weakest way to reach a fund, and it's the one most founders default to. Bring your contacts (founders, operators, angels, ex-colleagues) into [My Network](/docs/features/my-network), then click **Find warm connection** on a partner's card. Pioneer searches your researched contacts for the path: a portfolio founder who can vouch for you, an angel who co-invests with the fund, someone who worked with the partner directly. Each path comes with a confidence level, the type of connection, and a suggested two-line ask.
Two features earn their keep here specifically:
- **[Ask your network](/docs/features/my-network#ask-your-network-a-question)** in plain language: *"Who do I know who has raised from a European climate fund in the last two years?"*
- **[Share a link to your network](/docs/features/my-network#share-a-link-to-your-network)** with your co-founder or an advisor, so they can search your network for intro paths without an account and without seeing your contacts.
## Run the process on the board
Buckets and statuses track the funnel (researching, intro requested, first meeting, partner meeting, passed), and [sharing a pipeline](/docs/features/sharing) gives your co-founder or board a read-only view by link. Private [notes](/docs/features/my-network#add-contacts-to-your-network) on a contact are where the relationship detail belongs; they never feed research.
## Hand it to your agent
Your agent can keep the raise moving through the [API](/docs/api): refresh the investor pipeline weekly, flag funds that just led a round at your stage, and pull the warm paths for the ones you haven't approached yet. See [Use Pioneer With Your Agent](/docs/agents).
## Next steps
- [Create Your First Pipeline](/docs/first-pipeline)
- [Find the Right People](/docs/guides/people)
- [My Network](/docs/features/my-network)
- [Outbound](/docs/outbound) and [Partnerships](/docs/partnerships)
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Teams & Workspaces
URL: https://usepioneer.ai/docs/teams
## Your workspace is your company
When you sign up with your work email, Pioneer automatically places you in your company's workspace, based on your email domain. If a colleague signed up before you, you'll land in the same workspace they did, no invitation needed. If you're the first, Pioneer creates the workspace for you.
This is why Pioneer asks for a **work email**: personal addresses (Gmail, Outlook, and similar) can't anchor a shared workspace, so they can't be used to sign up.
## What your team shares
Everything in a workspace belongs to the team:
- **Pipelines and leads:** every pipeline in the workspace is visible to every member, along with its leads, research, and history
- **Credits and billing:** the workspace has one credit balance and one subscription; anyone's discovery runs draw from the same balance
- **Research:** what Pioneer learns for one member's pipeline is part of the shared workspace
If you want a private space for personal exploration, use a separate workspace: pipelines can't be hidden from teammates within a workspace.
## Inviting teammates
Teammates with your email domain can simply sign up and they'll arrive in your workspace automatically. You can also invite someone directly:
1. Open your workspace page from the sidebar
2. Go to the **Team** tab
3. Send an invitation to their email address
## Roles
Workspace members are either **admins** or **members**. Day-to-day work (creating pipelines, triaging leads, steering research) is the same for everyone; admin controls cover workspace-level settings.
## Related docs
- [Credits & Billing](/docs/credits): how the shared credit balance works
- [Working with Pipelines](/docs/pipelines): the boards your team collaborates on
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Credits & Billing
URL: https://usepioneer.ai/docs/credits
## How credits work
Pioneer runs on credits, and the rule is simple: **one credit = one lead**. You spend a credit each time Pioneer discovers a new lead for you or you import one. That's it.
Everything that happens *after* a lead lands on your board is free:
- **Enrichment is free:** adding properties, finding people and contact details, deep research
- **Criteria evaluations are free:** qualifying and re-qualifying leads against your criteria
- **Reviewing and managing your board is free:** approving, rejecting, and moving leads never costs anything
You only pay when Pioneer finds you a new lead. You never pay to learn more about a lead you already have.
## The free plan
Every new account starts with **50 free credits**, enough to generate 50 leads and get a real feel for lead quality. The free plan supports up to 3 teammates.
Free credits are a one-time grant; they don't renew monthly.
## The Pioneer AI Retainer
The retainer is **$99/month** and includes:
- **300 credits per month** (300 leads)
- Unlimited pipelines
- Unused credits roll over month to month (your balance can grow up to 1,000 credits)
- Email support from a human
Free vs. Retainer: what you get at each plan level
## What happens when you run out
When your balance hits zero, lead generation pauses: Pioneer stops discovering new leads until you top up or your monthly credits renew. **Nothing is lost.** Your pipelines, your board, and every lead you've already generated stay fully accessible, and enrichment on existing leads keeps working.
## Checking your balance
Your current credit balance is shown on your organization's **Subscription** page, along with your usage history.
## Next steps
- [Create Your First Pipeline](/docs/first-pipeline): put your credits to work
- [Refine Your Pipeline](/docs/guides/refining): get more signal from every batch
- [Troubleshooting & FAQ](/docs/troubleshooting): answers to common billing-adjacent questions
## Need help?
If you have questions, reach out to us at [support@pioneerclimate.com](mailto:support@pioneerclimate.com)
# Use Pioneer With Your Agent
URL: https://usepioneer.ai/docs/agents
## Humans: tell your agent to read this page
Guide me through https://usepioneer.ai/docs/agents so I can set up Pioneer AI.
## Agents: follow these instructions
If you are an agent reading this page, this section is your setup procedure. Do not try to do it silently, and do not ask your user to read this page: explaining Pioneer to them in their own terms is your job.
**a) Make sure your user has an account.** Ask them to sign up at [app.usepioneer.ai](https://app.usepioneer.ai/login) with Google or their work email if they have not already. Every plan, including the free tier, can use the API. Wait for them to confirm before continuing.
**b) Ask for a connection.** No agent can mint its own credential, so ask your user for one. Right after signup they land on a page with a label field and two buttons: **Create an API key** (for agents that run on a computer) and **Create an MCP server** (for chat assistants without one). Tell them which of the two you need and suggest a label (your own name is a good one, like "Claude Code"), then they press the button and paste the value back to you. Either value appears only when they press the button, and is shown once. The same two buttons live in the app for good, under the account menu, then **API and MCP**, where API keys and MCP servers are separate lists. If your user already pasted a credential, use it and do not ask for another.
**c) Configure yourself.** Store the key where your harness keeps secrets (an environment variable such as `PIONEER_API_KEY`, never a file you commit and never the chat transcript), read the [API reference](/docs/api) before making any call, and **offer to save a skill** so this setup survives past the current conversation. The section for your own harness is below.
**d) Create their first pipeline.** Setup is not finished until leads are coming in. Ask your user the one thing only they know, what they sell and who buys it, turn that into a goal, and create the pipeline yourself. Step by step in [The first pipeline](#the-first-pipeline) below.
**e) Offer to connect their network.** Pioneer can tell your user who they already know who could introduce them to a lead, but only once their network is in the product. Offer it, and follow [Connect their network](#connect-their-network) below if they say yes. Do not push: their contacts are private, and the feature is beta behind an allowlist.
## Set up API access (agents with a terminal)
Claude Code, OpenAI Codex, Cursor, Devin, Hermes, OpenClaw and any agent you built yourself can call Pioneer directly. This is the simpler path: no extra process, and the [full reference](/docs/api) is one page.
1. Put the key in the environment your commands run in: `export PIONEER_API_KEY=pioneer_sk_...`
2. Send it as a bearer token against `https://app.usepioneer.ai/api/v1`, for example `curl -H "Authorization: Bearer $PIONEER_API_KEY" https://app.usepioneer.ai/api/v1/pipelines`
3. Save the skill file below so the next session starts already configured.
4. Create one pipeline per goal, then read leads back and work the board. The [API reference](/docs/api) has every route.
If a call returns 401 or 403, stop and ask the user to check the key in the app rather than guessing at the auth scheme.
## Set up MCP access (chat-only assistants)
claude.ai, ChatGPT and other assistants without a computer of their own accept a connector instead. Pioneer's MCP server is a protocol adapter: every tool it exposes maps to one API endpoint, so there is no capability here that the API does not also have.
1. In the app, open the account menu, then **API and MCP**, then **Create MCP server** on the MCP servers box. Label it so you can tell your connectors apart later.
2. Copy the **MCP URL** shown right after creation. It looks like `https://app.usepioneer.ai/api/mcp/pioneer_sk_.../mcp`
3. Paste it into your assistant's connector settings. In claude.ai that is **Settings, then Connectors, then Add custom connector**. In ChatGPT it is the connector or custom tool section of settings.
MCP servers are listed separately from API keys on that page, and **MCP URL** on a row shows the URL again.
> **The MCP URL contains your API key.** Treat it like a password: never paste it into a shared conversation, never commit it, and revoke it on the API and MCP page if it leaks.
The [tool-to-route map, the inspector command, and the OAuth caveat](/docs/api#mcp-claudeai-and-other-mcp-native-assistants) live in the API reference.
## The first pipeline
A pipeline is one research goal: who to find, and why they would buy. Do not hand this back to your user as a form to fill in. Write the goal from what they told you, create it, and show them what came back.
1. Ask what they sell and who buys it. One sentence is enough, and it is the only thing you cannot infer.
2. `POST /pipelines { "goal": "..." }`. Phrase the goal specifically (a segment, a geography, a trigger), never as "find customers".
3. Discovery runs in the background. Poll `GET /pipelines/{id}/leads` no faster than every two seconds, and expect it to fill in over minutes rather than instantly.
4. Read one lead in full with `GET /leads/{entryId}`, then summarize a handful in your user's own terms: who the company is, why it matched, who to reach there.
5. Record their judgment as they give it, with `PATCH /leads/{entryId}` (status, bucket). That judgment is what teaches the pipeline, and it is wasted if it stays in your chat transcript.
If they would rather steer it themselves, the same thing is a form at [app.usepioneer.ai/pipelines](https://app.usepioneer.ai/pipelines), which also suggests niches based on what Pioneer already knows about them.
## Connect their network
My Network is your user's own private, researched network, and it is what turns a lead into a warm introduction: the lead, then the person behind the deal, then whoever your user already knows who can reach them.
**Check access first.** `GET /network/docs` returns the full agent guide for the feature as Markdown, or `403 forbidden` if the account does not have it. The feature is beta and allowlist-gated, so a 403 is a normal answer: say it is not enabled for their account yet and move on. If you do get the guide, read it before calling anything else under `/network`.
**Then fill it, source by source.** Nothing enters the network unless your user hands it over, so your job is to name the sources they have and offer to do the work. Every source ends the same way: one line per person, into `POST /network/contacts { "input": [...] }`, which answers `202` with `{ added, duplicates, enriched, invalid }`. Read `invalid` back to them (dead links, shared mailboxes like `info@`), then follow progress with `GET /network/contacts` and its `summary` block rather than asking them again.
A line identifies a person: a LinkedIn or X profile, any page they are identifiable from (own site, GitHub, Substack, a bio page), or an email address, bare or named (`Jane Doe `). Names alone are weak; always pair a name with a link or an address.
Below are the sources worth offering, strongest signal first. They are prompts your user can paste to you, or you can offer them in your own words. **Only ever send Pioneer the people. Never the message bodies, never the meeting contents, never the files.**
**1. LinkedIn connections export.** Their whole graph, in one file, and the single highest-volume source.
```text
I exported my LinkedIn connections. Read Connections.csv from my
Downloads folder and add every person to my Pioneer network.
```
Tell them where to get it: LinkedIn, then **Settings & Privacy**, then **Data privacy**, then **Get a copy of your data**, then **Connections**. The mail arrives within minutes. The CSV has `First Name, Last Name, URL, Email Address, Company, Position`: send the profile URL as the line, and the email when the URL is missing.
**2. Sent mail.** Who they actually email is stronger signal than who they are connected to.
```text
Go through the last two years of my sent mail, pull out the people I
emailed personally, and add them to my Pioneer network. Send Pioneer only
names and email addresses, never the contents of any email.
```
Skip automated senders (`noreply@`, `notifications@`, ticketing, newsletters) and shared mailboxes. Someone they emailed more than once, by hand, is a real tie.
**3. Calendar.** Meeting someone is a stronger tie than emailing them.
```text
Look through my calendar for the last two years, list everyone I have
actually met with (skip internal-only and all-day blocks), and add them
to my Pioneer network. Only the attendees, not the meeting titles or notes.
```
External attendees of small meetings are the gold here. Drop invites they declined, recurring internal standups, and anything with more than ~20 attendees.
**4. Phone contacts.** The address book is usually their oldest, most trusted layer.
```text
Export my phone contacts and add the ones with a real name and an email
or LinkedIn to my Pioneer network. Skip businesses and services.
```
**5. WhatsApp, iMessage, Telegram, Signal.** People they text are close ties, and the export is contacts-only by design.
```text
From my WhatsApp chats, list the individual people I message (not groups,
not businesses) and add the ones you can match to an email or a LinkedIn
profile to my Pioneer network. Do not read or share any message contents.
```
**6. X / Twitter.** Mutuals and DMs, not followers.
```text
Add the people I follow who also follow me on X, plus anyone I have DMed,
to my Pioneer network as their X profile URLs.
```
**7. Slack workspaces they share with outsiders.** Community and partner Slacks are dense with warm ties.
```text
Go through the shared and community Slack workspaces I am in, list the
external people I have DMed, and add them to my Pioneer network.
```
**8. CRM and investor tools.** Anything already curated is a clean import.
```text
Export my contacts from HubSpot (or Salesforce, Attio, Affinity, Pipedrive)
and add every person to my Pioneer network.
```
**9. GitHub, Discord and other work communities.** For technical users this is often where the real network lives.
```text
List the people I have collaborated with on GitHub (co-authors, reviewers,
maintainers of repos I contributed to) and add their GitHub profiles to my
Pioneer network.
```
**10. Alumni, cap table, cohort and Notion lists.** The lists they already maintain by hand.
```text
Here is my angel investor list / my YC batch directory / my university
alumni spreadsheet. Add everyone in it to my Pioneer network.
```
Whatever else they have access to counts too: Google Contacts, Superhuman, Luma or Partiful guest lists, Substack subscribers, a conference attendee list, an old CRM export. The rule is the same: one line per person, only the people.
**Then use it.** Once contacts are researched, ask the network plain questions on their behalf ("who can introduce me to battery OEMs?"). Warm paths on specific leads additionally need the `connect_to_leads` preference, which is off by default: ask before turning it on, never quietly.
They can do all of it by hand instead: **My Network** in the sidebar, then **Add contacts**. [My Network](/docs/features/my-network) is the human version of this section.
A user's network is theirs alone: never per organization, never visible to teammates, never exported anywhere by you.
## Claude.ai in a browser, step by step
If you use **claude.ai** (the web app), Pioneer connects as a custom connector. No API calls, no terminal, no skill file needed.
Claude in a browser cannot install itself, so this is the one path a human has to click through. Create the MCP server, copy the MCP URL beside it, then in claude.ai open **Settings**, then **Connectors**, then **Add custom connector**, and paste the URL. Claude can then create pipelines, read leads, and work your board on your behalf. Claude Code, which runs on your machine, uses the API path above instead.
## Which agents work
Whatever agent you already use is supported. The only requirement is an HTTP request with a bearer token, or a settings field that accepts a connector URL.
- **API path** (agents with a terminal): Claude Code, OpenAI Codex, Cursor, Devin, Hermes, OpenClaw, and anything you built yourself
- **MCP path** (chat-only assistants): claude.ai, ChatGPT, and other tools that only accept connectors
If yours is not named here it is still supported: the list is examples, not a compatibility matrix. Both paths use the same key, and there is nothing Pioneer-specific to install.
## Best practice: put Pioneer in a skill
Do not re-explain Pioneer to your agent every session. Save it once as a **skill**, the reusable instruction file most harnesses support (`.claude/skills/`, `.agents/skills/`, `AGENTS.md`, a custom prompt library, whatever yours uses), and the agent picks it up automatically from then on.
A good Pioneer skill does four things:
1. **Says where the key lives.** Read it from an environment variable such as `PIONEER_API_KEY`. Never paste a key into the skill file itself, and never commit it.
2. **Tells the agent how to get a key when there is none.** If the user pasted one, use it. Otherwise walk them through creating one in the app (account menu, then **API and MCP**), because no agent can mint one.
3. **Points at the API reference.** [`/docs/api`](/docs/api) is the whole contract: base URL, auth, endpoints, conventions. The skill should say to read it rather than guess routes.
4. **Names the job.** "Find and qualify leads matching X, keep the board current, report new relevant leads" beats a generic "use the Pioneer API".
Here is a skill you can copy as-is:
```markdown
# Pioneer (lead research)
Use Pioneer to find and qualify leads: https://usepioneer.ai/docs/api is the
full API reference. Read it before calling anything.
## Auth
Send `Authorization: Bearer $PIONEER_API_KEY` against https://app.usepioneer.ai/api/v1.
If `PIONEER_API_KEY` is unset, or a call returns 401/403, stop and ask the user
to create or fix the key in the app: account menu, then API and MCP, then
Create API key. The key is shown once, and every plan including the free tier
can create one. Never print the key back to them.
## How to work
- One pipeline per goal, phrased specifically: POST /pipelines { "goal": "..." }.
- Read results with GET /pipelines/{id}/leads, and one lead in full with
GET /leads/{entryId}.
- Act on leads with PATCH /leads/{entryId} (status, bucketId). That judgment is
what teaches the pipeline, so record it rather than keeping it in chat.
- Wrong researched value: POST /leads/{entryId}/mark-inaccurate.
Missing value: POST /leads/{entryId}/search-more.
- Warm introductions: GET /network/docs first, and treat 403 as "the account
does not have My Network". Contacts only ever enter the network from a
paste the user hands over: POST /network/contacts { "input": [...] }.
- Async endpoints return 202. Poll the matching GET, no faster than every 2s.
- Explain results to the user in their terms. Do not make them read the docs.
```
Once that file exists, "check Pioneer for new leads on the EU climate pipeline" is a complete instruction.
## What to hand your agent, and what to keep
Give your agent the API key and the goal. Keep the judgment: which leads are worth pursuing is the part Pioneer is built to hand back to you, and every approval or rejection your agent records on your behalf should be one you would have made yourself.
Start with [the API reference](/docs/api). If you want to understand what your agent is actually doing, [Your Pipeline & Board](/docs/pipelines) explains the product it is driving.
# API
URL: https://usepioneer.ai/docs/api
## Start here: instructions for agents
You are probably an AI agent whose human wants to use Pioneer AI. Guide them through setup:
1. Have them sign in at [https://usepioneer.ai](https://usepioneer.ai) (free tier available, no card needed).
2. Have them open **Account menu → API Keys** ([https://app.usepioneer.ai/api-keys](https://app.usepioneer.ai/api-keys)) and either **create an API key** (for REST) or **copy the MCP connector URL** (for MCP clients).
3. Connect: REST calls use `Authorization: Bearer ` against `https://app.usepioneer.ai/api/v1`. MCP clients (claude.ai custom connectors, or any MCP-capable tool, including sales tools that support MCP) take the connector URL directly. The connector URL contains the key: treat it like a password.
4. Read the endpoint reference below before calling anything. Never guess endpoints that are not documented here.
Everything a user can do in the app, you can do through this API: create and configure pipelines, read leads and their researched properties and people, record feedback, and more. Network features (My Network, asks, warm intros) need the network grant on the account: every account that already existed when the network rolled out has it, and a newer account can request it from the **My Network** page in the app. Those endpoints return an access error until the grant is in place, so tell your human to request it there, or to reply to any Pioneer email.
Most readers of this page are agents working on someone's behalf, so it is written for them.
The API has no self-serve signup for keys: the human you are working for has to do two things themselves, in the app, in this order:
1. **Have a Pioneer account.** They sign up at [usepioneer.ai](https://usepioneer.ai). Every plan, including the free tier, can use the API. You cannot create an account for them.
2. **Create a key themselves on the API Keys page.** Account menu (their avatar, bottom left) then **API Keys** then **Create key**. The raw key is shown **once** and stored only as a hash, so they must copy it then. It looks like `pioneer_sk_` followed by 40 characters.
Then they paste that key to you and you send it as a bearer token. A key acts as that user, so treat it like their password: never print it back, never commit it, and tell them to revoke it on the same page if it leaks.
If a call returns `401`, the key is wrong or revoked. If it returns `403`, the account is missing that feature (the network grant, or the connect-to-leads opt-in that warm intros on leads additionally need), which is an invite for a human to grant or request, not something to retry or work around.
If you use claude.ai, you can connect Pioneer as a custom connector through its MCP server. No need to make API calls by hand. See [Use Pioneer With Your Agent](/docs/agents) for setup steps.
## Instructions for agents
Read this section first. It contains everything needed to make a correct call.
- **Base URL:** `https://app.usepioneer.ai/api/v1`. Every path below is relative to it. The API lives on the app host only: calling `usepioneer.ai` or `www.usepioneer.ai` hits the main website and returns an HTML 404 page, not the JSON error shape below.
- **Auth:** every request sends a bearer token.
```
Authorization: Bearer pioneer_sk_xxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxxx
```
- **Keys impersonate their owner.** A key acts as the user it was minted for, with that user's permissions. It can never do anything that user could not do in the app, and it only ever sees that user's organization, contacts, and asks.
- **Error envelope:** every error has one shape.
```json
{ "error": { "code": "unauthorized", "message": "human readable detail" } }
```
| HTTP | `code` | When |
| ---- | ------ | ---- |
| 400 | `invalid_request` | Missing or invalid body / query params |
| 401 | `unauthorized` | Missing, malformed, unknown, or revoked key |
| 402 | `paywall` | Free-plan pipeline cap or a credit paywall blocks the action |
| 403 | `forbidden` | The feature is not enabled for this account (for example the network grant) |
| 404 | `not_found` | The resource does not exist or is not visible to the key's user |
| 500 | `internal` | Unexpected server error |
- **IDs** are UUIDs unless stated otherwise. A malformed id returns `400`; an id you cannot see returns `404`. Never guess an id: get it from a list endpoint.
- **Pagination** is cursor based where it exists (`GET /pipelines/{pipelineId}/leads`): pass `limit` (default 50, max 200) and feed `nextCursor` back as `cursor`. `nextCursor` is `null` on the last page.
- **Async endpoints** answer `202` and do the work in the background. Poll the matching read endpoint instead of assuming completion, and poll no faster than every 2 seconds.
- **Batch your writes**, respect `429` and its `Retry-After` header, and back off rather than retrying in a tight loop.
- **Only the endpoints on this page exist for you.** Do not guess other routes, parameters, or fields. If something you need is not here, it is not part of the public API.
- **This is v1 and still evolving.** Endpoints and fields may be added or changed. Re-read this page rather than relying on a cached copy.
### Helping your user get value out of Pioneer
The API mirrors the product, so a good result depends on the same things a good result in the app depends on. Two things matter more than call volume:
- **A pipeline is one question, asked well.** The `goal` you pass to `POST /pipelines` becomes the criteria Pioneer researches against. "Series A climate hardware founders in Europe" works; "leads" does not. One goal per pipeline: criteria that describe two targets qualify neither. See [Your Pipeline & Board](/docs/pipelines) and [Criteria](/docs/concepts/criteria).
- **Judgment is the feedback loop.** Approving, rejecting, and moving leads through `PATCH /leads/{entryId}` is what teaches the pipeline, exactly as it does on the board. Use `mark-inaccurate` for wrong researched values and `search-more` for missing ones instead of silently working around bad data.
Each newly discovered lead costs one credit; reading, enriching, and re-qualifying leads you already have is free. [Credits & Billing](/docs/credits) has the details, and the rest of this Help Center is the product explanation to fall back on when your user asks what something means.
Working out of an agent harness such as Claude Code, Codex, Devin, or Hermes? [Use Pioneer With Your Agent](/docs/agents) covers the setup, including the skill you should offer to save so this does not have to be re-explained every session.
## Identity
### `GET /me`
Who the key belongs to, plus the plan limits that decide whether writes will be paywalled.
```bash
curl -s https://app.usepioneer.ai/api/v1/me \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"user": { "id": "uuid", "email": "user@company.com", "name": "Jane Doe" },
"org": { "id": "uuid", "name": "Acme", "slug": "acme", "url": "https://app.usepioneer.ai/organizations/acme" },
"limits": {
"pipelineCount": 2,
"pipelineLimit": 3,
"isSubscriber": false,
"balanceCredits": 1200,
"isPaywalled": false
}
}
```
## Pipelines
### `POST /pipelines`
Create a pipeline from a free-text goal. Same as the create flow in the app: criteria generation and lead discovery start automatically.
- `goal` (string, **required**): what to find, in plain language.
- `title` (string, optional): defaults to an auto-generated title.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"goal": "Series A climate hardware founders in Europe", "title": "EU climate founders"}'
```
```json
{ "id": "pipeline-uuid", "url": "https://app.usepioneer.ai/pipelines/pipeline-uuid" }
```
Returns `201`, or `402` when the free-plan pipeline limit is reached.
### `GET /pipelines`
List the organization's pipelines, newest first. Archived pipelines are excluded unless you pass `?includeArchived=true`; each row carries `isArchived`.
```bash
curl -s "https://app.usepioneer.ai/api/v1/pipelines?includeArchived=true" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"pipelines": [
{
"id": "uuid",
"title": "EU climate founders",
"emoji": "🌍",
"status": "Ready",
"isArchived": false,
"entryCount": 42,
"createdAt": "2026-07-20T12:00:00.000Z",
"url": "https://app.usepioneer.ai/pipelines/uuid"
}
]
}
```
### `GET /pipelines/{pipelineId}`
Full pipeline detail, including description, structured criteria, and properties.
```bash
curl -s https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
### `PATCH /pipelines/{pipelineId}`
Edit pipeline metadata. Body accepts any of `title`, `emoji`, `description` (at least one required); `name` works as an alias for `title`. Strings are trimmed and an empty `title` is rejected with `400`. Responds with the same shape as `GET /pipelines/{pipelineId}`.
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"title": "EU climate founders", "emoji": "🌍", "description": "Series A hardware"}'
```
### `POST /pipelines/{pipelineId}/archive` and `/unarchive`
Archive a pipeline (which frees a free-plan pipeline slot) or restore it. Same as the "Archive Pipeline" action in the app.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/archive \
-H "Authorization: Bearer $PIONEER_API_KEY"
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/unarchive \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "id": "uuid", "isArchived": true, "url": "https://app.usepioneer.ai/pipelines/uuid" }
```
### `POST /pipelines/{pipelineId}/find-leads`
Ask for another batch of leads. Optional body `{ "leadCount": 20 }` (1 to 100, default 10). Discovery runs in the background, so the call answers `202`; read results with `GET /pipelines/{pipelineId}/leads`.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/find-leads \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"leadCount": 20}'
```
```json
{ "ok": true }
```
Each newly discovered lead is billed like any other, so this is the call that can return `402 paywall`. Use it to ask for more leads programmatically: same as the **more leads** button on the board, but without needing to be in the UI.
### `GET /pipelines/{pipelineId}/leads`
Paginated leads for a pipeline.
Query params:
- `limit` (default 50, max 200)
- `cursor` (opaque; the `nextCursor` from the previous page)
- `status` (optional; filter by entry status)
```bash
curl -s "https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/leads?limit=50" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"leads": [
{
"id": "entry-uuid",
"name": "Acme Corp",
"url": "https://acme.com",
"status": "analyzed",
"bucketId": "uuid",
"score": 0.92,
"tldr": "…",
"propertyValues": { },
"appUrl": "https://app.usepioneer.ai/pipelines/PIPELINE_ID?entry=entry-uuid"
}
],
"nextCursor": "50"
}
```
## Leads
### `GET /leads/{entryId}`
Everything about one lead: status, score, property values, latest update, artifacts, and the associated people with their contact details.
```bash
curl -s https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
#### Email deliverability: draft only to a verified address
Every `email` contact carries a `verification` block, and the lead carries an `outreach` block that says outright who may be written to.
`verification.status` is one of:
- `verified`: the mailbox was confirmed. The only status with `safeToSend: true`.
- `catch_all`: the domain accepts every address, so this specific mailbox cannot be confirmed. Deliverability is unproven.
- `invalid`: the mailbox does not exist. Mail to it hard-bounces.
- `unverified`: no check has produced a verdict (never checked, monthly cap hit, or no API key configured).
The `outreach` block:
```json
{
"outreach": {
"provider": "millionverifier",
"draftable": false,
"verifiedRecipients": [],
"blockedRecipients": [
{
"personId": "person-uuid",
"name": "Spencer Parikh",
"email": "spencer.parikh@devcommx.com",
"status": "unverified",
"message": "NOT verified. Treat this address as a guess, not a fact."
}
],
"guidance": "No verified-deliverable email exists on this lead."
}
}
```
Contract for anything that drafts outreach:
1. Address a draft **only** to an address with `safeToSend: true`, in practice the person's `draftableEmail`, which is `null` unless an address passed verification.
2. When `outreach.draftable` is `false`, create the draft with the recipient **blank**, flag it as needing a verified email, and report which addresses failed verification and why.
3. Use `POST /leads/{entryId}/search-more` with `{"personId": "...", "field": "email"}` to chase a real address for a lead that has none.
### `PATCH /leads/{entryId}`
Act on a lead the way the board does. Body needs at least one field:
- `status`: one of `approved`, `rejected`, `done`, `recommended`. Anything else returns `400` listing the allowed set.
- `archived`: boolean.
- `bucketId`: a bucket UUID, or `null` to send the lead back to the leftmost stage (the **Relevant** stage, unless it has been renamed). Setting `bucketId` does **not** change `status`, and the bucket must belong to the lead's own pipeline (otherwise `400`). Get bucket ids from `GET /pipelines/{pipelineId}/board`.
> `recommended` is the API's name for a lead that is **relevant** (every MUST criterion met). The board shows this tier as "Relevant".
Board semantics: `status: "rejected"` also archives the lead unless you pass `archived: false` explicitly. Other statuses leave the archive state alone unless `archived` is given. A status-change message is recorded on the lead's timeline, exactly as in the app. The response is the same shape as `GET /leads/{entryId}`.
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"status": "rejected"}'
# Move the lead into a custom bucket (status unchanged)
curl -s -X PATCH https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"bucketId": "bucket-uuid"}'
# Return the lead to the leftmost stage (Relevant)
curl -s -X PATCH https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"bucketId": null}'
```
### `GET /leads/{entryId}/notes`
The user's notes on a lead, newest first, grouped by note key. Notes are how outreach state lives on a lead: a key in `versioned` mode holds a current draft (older versions hidden but kept), a key in `log` mode is a running record of actions taken ("sent intro email", "scheduled a meeting"). Keys are the user's own; read them to learn which ones this lead uses.
Query params:
- `includeHistory` (boolean, optional): include superseded versions of versioned notes.
```bash
curl -s https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/notes \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"notes": [
{
"key": "email-draft",
"mode": "versioned",
"label": "Draft email",
"current": {
"legoId": "uuid",
"key": "email-draft",
"mode": "versioned",
"label": "Draft email",
"text": "Hi team…",
"createdAt": "2026-08-11T12:00:00Z",
"author": {
"userId": "uuid",
"email": "user@company.com",
"name": "Jane Doe",
"avatarUrl": "https://…"
},
"channel": "api",
"isCurrent": true
},
"history": []
}
]
}
```
### `POST /leads/{entryId}/notes`
Write a note on a lead. `key` groups related notes and is entirely the caller's choice. A new key defaults to mode `"log"` (each note appends); pass `"versioned"` when a newer note should replace the older one. Once a key exists its mode is fixed, and passing a conflicting mode is an error.
Body fields:
- `key` (string, **required**): note key or name. A free-text key like `"Draft email"` is slugified the same way the UI does, so API and UI notes with the same name land on the same key. Use `"updates"` for the unnamed log that the Notes Bar writes to by default.
- `text` (string, **required**): the note body, as markdown.
- `mode` (`"log"` | `"versioned"`, optional): only used on a new key. Omit to mirror the UI's convention, where `"updates"` is a log and any other key is versioned.
- `label` (string, optional): override the displayed label for this key.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/notes \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"key": "email-draft", "text": "Hi Dan, I saw your talk at…", "mode": "versioned"}'
```
Responds `201` with the note that was written, in the same shape as `current` above.
Notes are written straight to the lead, with no workflow run, no artifact, and no credit cost, so a note lands as fast as typing. They are not research content (see legos below) and the API exposes no edit or delete: update a note by writing a new `versioned` note under the same key, or let the log stand as the record.
### `GET /leads/{entryId}/legos`
The lead's research content as atomic content blocks, ordered by path. Each lego is a typed, self-contained block (a TL;DR, a deep dive topic, a criterion narrative) assembled into views by namespace.
Query params:
- `prefix` (string, optional): narrow to one namespace (`summary`, `deepdive`, `notes`, `properties`). Embeddings are never returned.
```bash
curl -s "https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/legos?prefix=summary" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"legos": [
{
"id": "uuid",
"path": "summary.tldr",
"name": "TL;DR",
"content": { },
"source": "aggregate-decision-step",
"metadata": { },
"createdAt": "2026-08-11T12:00:00Z",
"updatedAt": "2026-08-11T12:00:00Z"
}
]
}
```
Legos are the building blocks of everything Pioneer writes about a lead: the summary, deep dives, criterion evidence, and property display. They exist independently of one another, so re-enriching a property does not touch the summary. Most agents should read notes (above) for outreach state and `GET /leads/{entryId}` for the verdict; legos are granular research content for advanced use.
### `POST /leads/{entryId}/mark-inaccurate`
Flag a researched value as **wrong**. The value is cleared, recorded as rejected so re-research never restores it, and a targeted re-enrich is queued to find a correct replacement. Same as "mark inaccurate" in the app.
Send **one** of two body shapes:
- **Scalar property:** `{ "propertyId": "" }`, using an id from the lead's `propertyValues` map. Person-type properties are rejected here.
- **Person field:** `{ "personId": "", "field": "" }`, where `field` is one of `avatar`, `email`, `phone`, `linkedin`, `x`, `about`, `news`. The person must be associated with the lead.
```bash
# Reject a wrong email on a person, then re-research it
curl -s -X POST https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/mark-inaccurate \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"personId": "person-uuid", "field": "email"}'
# Reject a wrong scalar property value
curl -s -X POST https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/mark-inaccurate \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"propertyId": "property-uuid"}'
```
```json
{ "ok": true, "entryId": "entry-uuid", "status": "re_enrich_queued" }
```
`400 invalid_request` covers a bad body, a property that has no value, a person-type property passed as `propertyId`, and a lead that is already being enriched (retry once it settles).
### `POST /leads/{entryId}/search-more`
Ask for another research pass on a field that came back **not found**. Nothing is cleared: the research agent is simply biased to spend its budget on this field first, while still picking up other missing fields. Same as "search harder" in the app. Use this for empty fields, and `mark-inaccurate` for wrong ones.
Body shapes are the same two as `mark-inaccurate`, except the scalar property must currently have **no** value.
```bash
# Search harder for a person's missing LinkedIn
curl -s -X POST https://app.usepioneer.ai/api/v1/leads/$ENTRY_ID/search-more \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"personId": "person-uuid", "field": "linkedin"}'
```
```json
{ "ok": true, "entryId": "entry-uuid", "status": "re_enrich_queued" }
```
## Board organization
Read and reorganize a pipeline's board: its columns, custom buckets, and the Done column. To move leads between columns, use `status` and `bucketId` on `PATCH /leads/{entryId}`.
### `GET /pipelines/{pipelineId}/board`
The whole board in render order, which is the map an agent needs before it moves anything. Returns the built-in **Leads** (`recommended` and `not_recommended`) and **Rejected** (archived) columns, plus custom buckets (the first of which is the seeded **Relevant** stage) and the **Done** column interleaved by sort order. Approved leads that carry no `bucketId` yet are counted in the leftmost stage, exactly as the board shows them.
- `done.title` is the custom Done-column title, falling back to `"Done"`, so a renamed column is self-describing.
- Counts exclude archived entries, except for the Rejected column, which counts them. They match what the board shows in the app.
```bash
curl -s https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/board \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"columns": [
{ "type": "leads", "title": "Leads", "statuses": ["recommended", "not_recommended"], "count": 12 },
{ "type": "bucket", "id": "relevant-uuid", "title": "Relevant", "description": null, "sortOrder": 0, "count": 17 },
{ "type": "bucket", "id": "bucket-uuid", "title": "Contacted", "description": "…", "sortOrder": 1, "count": 5 },
{ "type": "done", "title": "Won", "description": "…", "sortOrder": 2, "statuses": ["done"], "count": 10 },
{ "type": "rejected", "title": "Rejected", "count": 8 }
]
}
```
### `POST /pipelines/{pipelineId}/buckets`
Create a custom stage. Body: `title` (required, non-empty, trimmed) and optional `description`.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/buckets \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"title": "Contacted", "description": "Move a lead here after first outreach."}'
```
```json
{ "id": "bucket-uuid", "title": "Contacted", "description": "Move a lead here after first outreach.", "sortOrder": 0 }
```
### `PATCH /buckets/{bucketId}`
Rename or re-describe a bucket. Body needs at least one of `title` (non-empty, trimmed) or `description` (string, or `null` to clear).
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/buckets/$BUCKET_ID \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"title": "Replied", "description": "Move a lead here once they reply."}'
```
### `DELETE /buckets/{bucketId}`
Delete a bucket. Its leads fall back to the leftmost stage with `bucketId` cleared; no lead is ever deleted by this.
```bash
curl -s -X DELETE https://app.usepioneer.ai/api/v1/buckets/$BUCKET_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "ok": true }
```
### `PATCH /pipelines/{pipelineId}/done-column`
Rename or re-describe the Done column. Body needs at least one of `title` (non-empty, trimmed) or `description` (string, or `null`). `title` falls back to `"Done"` when it was never set.
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/done-column \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"title": "Won"}'
```
```json
{ "title": "Won", "description": null }
```
### `PATCH /pipelines/{pipelineId}/board-order`
Set the left-to-right order of the movable columns, which are the custom buckets and the Done column. Body `{ "orderedColumnIds": string[] }`, where each id is a bucket UUID and the literal `"__done__"` stands for the Done column. The built-in Leads and Rejected columns are fixed and are not included.
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/board-order \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"orderedColumnIds": ["bucket-uuid", "__done__", "bucket-uuid-2"]}'
```
Returns the new board, same shape as `GET /pipelines/{pipelineId}/board`.
## Sharing
Read-only, revocable guest access to a pipeline. A share is addressed either to an **email** (Pioneer emails that person their personal link) or to a **name** (a link you distribute yourself, for people whose email you do not have). Guests never become Pioneer users and can only read.
### `GET /pipelines/{pipelineId}/shares`
List active shares, newest first.
```bash
curl -s https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/shares \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"shares": [
{
"id": "share-uuid",
"accessMode": "link",
"recipientEmail": null,
"name": "Anna from Breakthrough",
"url": "https://app.usepioneer.ai/share/8Kq2...",
"createdAt": "2026-07-30T10:00:00.000Z",
"lastViewedAt": null
}
]
}
```
`url` is present for `link` shares only: an email share's token is the credential of exactly one address and is never returned.
### `POST /pipelines/{pipelineId}/shares`
Share the pipeline with one person. Body `{ "recipient": string, "message"?: string }`.
- `recipient` (**required**): an email address, or any other text, which becomes the link's name.
- `message` (optional, up to 500 characters): included in the invite email, ignored for named links.
```bash
# Email invite
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/shares \
-H "Authorization: Bearer $PIONEER_API_KEY" -H "Content-Type: application/json" \
-d '{"recipient": "guest@company.com", "message": "Here is the pipeline we discussed."}'
# Named personal link
curl -s -X POST https://app.usepioneer.ai/api/v1/pipelines/$PIPELINE_ID/shares \
-H "Authorization: Bearer $PIONEER_API_KEY" -H "Content-Type: application/json" \
-d '{"recipient": "Anna from Breakthrough"}'
```
Returns `201`, and it is idempotent: the same email resends the invite and the same link name (case-insensitive) returns the existing link, so neither creates a second share. An email share carries `"emailed": false` when the invite failed to send, so you can retry. A half-typed address such as `guest@company` is rejected with `400` rather than silently becoming a link name.
### `DELETE /shares/{shareId}`
Revoke a share. The link stops working on the guest's next request. An unknown or already-revoked share returns `404`.
```bash
curl -s -X DELETE https://app.usepioneer.ai/api/v1/shares/$SHARE_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "id": "share-uuid", "revoked": true }
```
## My Network
Programmatic access to My Network: the contacts you ingest, the research Pioneer runs on them, the questions you ask of your network, and your calendar source.
Two rules apply to every endpoint in this section:
1. **My Network must be enabled for the account.** Otherwise every call returns `403 forbidden` with the message `Network access is not enabled for this account.`
2. **Network data is per user, never per organization.** A key only sees and changes its own user's contacts, asks, and preferences. There is no aggregate or cross-user view.
### `GET /network/contacts`
List contacts with a status summary computed over the full set. Optional filters narrow `contacts`, never the `summary`:
- `status`: one of `none`, `queued`, `running`, `done`, `failed`, or the virtual `stalled` (a `running` contact untouched past the stuck threshold; a `queued` one is waiting behind the concurrency limit, not stuck).
- `source`: `manual` for contacts pasted in (profile URLs or email addresses), or `synced` for contacts from Google Calendar.
```bash
curl -s "https://app.usepioneer.ai/api/v1/network/contacts?status=stalled&source=synced" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"contacts": [
{
"id": "contact-uuid",
"email": "jane@acme.com",
"display_name": "Jane Doe",
"source": "google_calendar",
"linkedin_url": "https://linkedin.com/in/janedoe",
"company": "Acme",
"role": "VP Eng",
"research_status": "done",
"researched_at": "2026-07-30T12:00:00.000Z"
}
],
"summary": {
"total": 42,
"byStatus": { "none": 3, "queued": 5, "running": 1, "done": 30, "failed": 3 },
"stalled": 2
}
}
```
### `GET /network/contacts/{contactId}`
One contact by id.
```bash
curl -s https://app.usepioneer.ai/api/v1/network/contacts/$CONTACT_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "contact": { "id": "contact-uuid", "display_name": "Jane Doe", "research_status": "done" } }
```
### `POST /network/contacts`
Add contacts from a paste. `input` is either a raw blob or newline list (string) or an array of lines, each line one person as:
- a profile URL: LinkedIn or X/Twitter,
- any other page one person is identifiable from (personal site, GitHub, Substack, faculty bio), or
- an email address, bare (`jane@acme.com`) or named (`Jane Doe `), which is what a sent-mail or CRM export carries. The address is the research anchor and the name beside it is kept verbatim.
Extraction tolerates mixed text; rows are deduped both within the batch and against existing contacts (calendar-synced ones by address), then queued for research.
Returns `202` with `{ added, duplicates, enriched, invalid }`; `invalid` holds the tokens that identify nobody (a broken link, or a shared mailbox like `info@`). Re-pasting an address you already have WITH a name (`Jane Doe `) is not a duplicate: it names the contact and re-runs research, which is how an address that could not resolve on its own gets a person, counted in `enriched`.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/contacts \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"input": ["https://linkedin.com/in/janedoe", "Jane Doe ", "https://x.com/johnroe"]}'
```
```json
{ "added": 2, "duplicates": 0, "enriched": 0, "invalid": [] }
```
`invalid` echoes back every token that tried to identify a person but couldn't: a link that resolves to no human, or a shared mailbox (`info@`, `no-reply@`, `careers@`), which is a company rather than a person.
Empty or missing `input` returns `400 invalid_request`, as does a paste with no identifiable person in it: `added: 0` with an empty `invalid` is never a successful answer, so an unattended agent cannot mistake a dropped import for a done one.
### `DELETE /network/contacts/{contactId}`
Remove one contact. Returns `204` with no body.
```bash
curl -s -X DELETE https://app.usepioneer.ai/api/v1/network/contacts/$CONTACT_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
### `POST /network/contacts/{contactId}/retry-research`
Re-queue research for one contact. The contact needs an identity anchor, a profile/site URL or an email address, otherwise `400 invalid_request`. Returns `202`.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/contacts/$CONTACT_ID/retry-research \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "ok": true, "contactId": "contact-uuid" }
```
### `POST /network/sweep`
Recovery for a network that has drifted: backfills avatars for faceless contacts and re-queues every contact that was never researched, failed, stalled, or went stale. Returns `202`.
- `force` defaults to `true`, which also re-researches contacts that already have a full profile. On a large network that is a second full research pass, so pass `force=false` to pick up only dropped work.
```bash
curl -s -X POST "https://app.usepioneer.ai/api/v1/network/sweep?force=false" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "ok": true }
```
### `POST /network/asks`
Ask a one-shot question of your own network. `question` is 1 to 500 characters. The work runs in the background, so the call returns `202` with the run's id; poll it for progress. One run at a time per user: asking while another is still running returns `400`.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/asks \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"question": "Who in my network knows the founders at Acme?"}'
```
```json
{ "id": "ask-uuid" }
```
### `GET /network/asks`
List your asks, newest first, each with its matches. Optional `?limit=` caps the count.
```bash
curl -s "https://app.usepioneer.ai/api/v1/network/asks?limit=20" \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "asks": [ { "id": "ask-uuid", "question": "Who knows Acme?", "status": "done", "matches": [] } ] }
```
### `GET /network/asks/{id}`
One ask with its matches and progress fields. Poll until `status` leaves `running`.
```bash
curl -s https://app.usepioneer.ai/api/v1/network/asks/$ASK_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "ask": { "id": "ask-uuid", "status": "running", "stage": "triage", "matches": [] } }
```
### `POST /network/asks/{id}/retry`
Re-run a previous ask as a new run, since history is append-only. Returns `202` with the new run's id.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/asks/$ASK_ID/retry \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "id": "new-ask-uuid" }
```
### `POST /network/asks/{id}/cancel`
Stop a running ask and free the one-run slot. Idempotent: a no-op on a finished run.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/asks/$ASK_ID/cancel \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "ok": true }
```
### `DELETE /network/asks/{id}`
Delete an ask from history, cancelling it first if it is still running. Returns `204` with no body.
```bash
curl -s -X DELETE https://app.usepioneer.ai/api/v1/network/asks/$ASK_ID \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
### `GET /network/preferences`
Your network preferences. A never-toggled account reads `false`.
```bash
curl -s https://app.usepioneer.ai/api/v1/network/preferences \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{ "connect_to_leads": false }
```
### `PATCH /network/preferences`
Update `connect_to_leads`, which must be a boolean. Returns the full updated preferences.
```bash
curl -s -X PATCH https://app.usepioneer.ai/api/v1/network/preferences \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"connect_to_leads": true}'
```
```json
{ "connect_to_leads": true }
```
### `GET /network/calendar`
The Google Calendar source: connection state and sync status in one call. `connection.status` is `connected` or `needs_consent`, and `source` is `null` until the first sync.
```bash
curl -s https://app.usepioneer.ai/api/v1/network/calendar \
-H "Authorization: Bearer $PIONEER_API_KEY"
```
```json
{
"connection": { "status": "connected" },
"source": { "sync_status": "idle", "last_synced_at": "2026-07-30T12:00:00.000Z" }
}
```
### `POST /network/calendar/sync`
Trigger a calendar sync. Optional `{ "full": true }` forces a full re-sync instead of the incremental default. Returns `202`, or `400 invalid_request` when the calendar is not connected.
```bash
curl -s -X POST https://app.usepioneer.ai/api/v1/network/calendar/sync \
-H "Authorization: Bearer $PIONEER_API_KEY" \
-H "Content-Type: application/json" \
-d '{"full": true}'
```
---
## MCP (claude.ai and other MCP-native assistants)
The same API is available through a remote [Model Context Protocol](https://modelcontextprotocol.io) server, so assistants like claude.ai can call Pioneer as a tool without manual HTTP setup. [Use Pioneer With Your Agent](/docs/agents) covers when to pick MCP over the API.
**Connector URL template:**
```
https://app.usepioneer.ai/api/mcp/YOUR_API_KEY_HERE/mcp
```
Replace `YOUR_API_KEY_HERE` with the key from **API Keys** in your account menu. The key is in the path because claude.ai has no field for one, so treat the whole URL like a password.
**Design:** the MCP server is a **protocol adapter only**. Every tool forwards to exactly one `/api/v1` endpoint, so behavior, gating, and error messages have a single definition. Nothing may be added to the MCP server that the HTTP API cannot already do: if a capability is missing, add it to the API first.
**Tools map:** the MCP server mirrors the full v1 API surface. Below is the complete tool map:
| MCP tool | Corresponding API route |
| -------- | ----------------------- |
| `whoami` | `GET /me` |
| `list_pipelines` | `GET /pipelines` |
| `create_pipeline` | `POST /pipelines` |
| `get_pipeline` | `GET /pipelines/{pipelineId}` |
| `archive_pipeline` | `POST /pipelines/{pipelineId}/archive` |
| `update_pipeline` | `PATCH /pipelines/{pipelineId}` |
| `get_pipeline_board` | `GET /pipelines/{pipelineId}/board` |
| `list_leads` | `GET /pipelines/{pipelineId}/leads` |
| `get_lead` | `GET /leads/{entryId}` |
| `move_lead` | `PATCH /leads/{entryId}` |
| `mark_inaccurate` | `POST /leads/{entryId}/mark-inaccurate` |
| `search_more_leads` | `POST /leads/{entryId}/search-more` |
| `get_lead_legos` | `GET /leads/{entryId}/legos` |
| `list_lead_notes` | `GET /leads/{entryId}/notes` |
| `add_lead_note` | `POST /leads/{entryId}/notes` |
| `find_leads` | `POST /pipelines/{pipelineId}/find-leads` |
| `import_leads` | `POST /pipelines/{pipelineId}/import` |
| `list_properties` | `GET /pipelines/{pipelineId}/properties` |
| `create_property` | `POST /pipelines/{pipelineId}/properties` |
| `update_property` | `PATCH /pipelines/{pipelineId}/properties/{propertyId}` |
| `delete_property` | `DELETE /pipelines/{pipelineId}/properties/{propertyId}` |
| `list_criteria` | `GET /pipelines/{pipelineId}/criteria` |
| `update_criteria` | `PATCH /pipelines/{pipelineId}/criteria` |
| `create_bucket` | `POST /pipelines/{pipelineId}/buckets` |
| `update_bucket` | `PATCH /buckets/{bucketId}` |
| `delete_bucket` | `DELETE /buckets/{bucketId}` |
| `update_done_column` | `PATCH /pipelines/{pipelineId}/done-column` |
| `update_board_order` | `PATCH /pipelines/{pipelineId}/board-order` |
| `list_shares` | `GET /pipelines/{pipelineId}/shares` |
| `create_share` | `POST /pipelines/{pipelineId}/shares` |
| `delete_share` | `DELETE /shares/{shareId}` |
| `list_network_contacts` | `GET /network/contacts` (needs the network grant) |
| `find_warm_paths` | `GET` / `POST /leads/{entryId}/warm-paths` (needs the network grant) |
| `send_feedback` | `POST /feedback` |
**OAuth** is not available yet. Until then, use the key-in-path URL above.
Debug a connector with the MCP inspector:
```bash
npx @modelcontextprotocol/inspector
# transport: Streamable HTTP, URL:
```
# Troubleshooting & FAQ
URL: https://usepioneer.ai/docs/troubleshooting
## Leads and processing
### A lead has been stuck in Incoming for a long time
Leads in the Incoming area show live progress while Pioneer researches them. If one stalls or fails, a warning icon appears next to it. Hover to see what went wrong, and click **Retry** to run it again. Retrying is safe: it re-runs the research without creating a duplicate.
### I tried to add leads and got "A lead search is already running for this pipeline"
Working as intended: a pipeline runs **one lead-adding job at a time**, a search or an import, never both at once. This keeps each batch clean so you can review it before the next one starts. Wait for the running job to finish (you'll see it complete in the Incoming area), then start yours from **more leads**. If a job stalls, the block clears itself after a short while. Other pipelines aren't affected; the rule is per pipeline.
### My import says "Reading your list…": is it stuck?
No, that's the parse stage. Pioneer is reading what you pasted and working out who each line refers to. Within a few seconds each lead from your list should appear as a muted row marked *queued*, and rows then fill in with live progress as research runs. If the queued rows never appear, check that your list has one lead per line and start the import again. See [Import Your Own Leads](/docs/features/import).
### A lead's email, photo, or other detail is wrong
Don't just ignore it, flag it. Hover over the wrong value, click the small trash icon that appears, and confirm **Redo?**. Pioneer clears the value, researches a replacement for that specific field, and permanently remembers the rejected value so re-research can never bring it back. This works on person details (photo, email, phone, LinkedIn, X, personal website, bio, news) and on any property value. Full details: [Correct Pioneer's Research](/docs/guides/accuracy).
### No new leads are appearing
A few things to check, in order:
1. **Is a search running?** The Leads column header shows an indicator while Pioneer is finding leads. If nothing is running, click **more leads** in the Leads column header and start a search.
2. **Are your criteria too strict?** If Pioneer searches but little arrives, your MUST criteria may be filtering almost everything out. See [Refine Your Pipeline](/docs/guides/refining).
3. **Have you hit your plan's lead limit?** When you're out of credits, lead generation pauses until you top up or your monthly credits renew. See [Credits & Billing](/docs/credits). Everything already on your board stays fully accessible.
### Discovery is taking a while
That's often a good sign. Pioneer explores iteratively (following sources, checking evidence, qualifying as it goes) rather than dumping a database query. Initial leads usually arrive quickly; thorough coverage of a space takes longer. Check back after a few hours for the full picture. How the search actually works: [How Pioneer Finds Leads](/docs/concepts/discovery).
### I imported the same company twice and got two leads
Pioneer deduplicates by resolved URL. If the same company enters via two different URLs (say, its homepage and its LinkedIn page), it can appear twice. Reject the copy you don't want; rejecting never deletes data.
### Pioneer matched the wrong company
This usually happens when a name or URL is ambiguous: two companies with the same name, or a link to an aggregator page rather than the company itself. When importing, prefer the lead's own website or LinkedIn page over directory links. If a discovered lead is simply wrong, reject it; that feedback helps you tighten criteria too.
Quick troubleshooting decision tree
## Results and relevance
### A lead I like isn't relevant
The relevance rule is mechanical: a lead is **relevant** only when *every* MUST criterion is met. Open the lead and check its criteria breakdown. You'll see exactly which MUST failed and the evidence Pioneer found. If you disagree with the rule rather than the lead, edit the criterion: it's stricter than what you actually believe. See [Refine Your Pipeline](/docs/guides/refining).
### Lots of criteria come back "Inconclusive"
Inconclusive means Pioneer couldn't find enough public evidence either way. It's harmless on a SHOULD, but a MUST passes only on affirmative evidence, so an inconclusive MUST counts as not met and disqualifies the lead. If one criterion is inconclusive across many leads, it probably isn't answerable from public information (exact revenue, internal tooling, private plans) or is phrased as something no evidence could confirm ("must not be an agency"). Rewrite it around signals the web can verify: funding announcements, job postings, published case studies, press. See [Write rules that can be confirmed, not just contradicted](/docs/concepts/criteria#write-rules-that-can-be-confirmed-not-just-contradicted).
### The results don't match what I asked for
Pioneer follows your written description and criteria, not intent it can't see. The fix is almost always to make the words match the intent: steer ("exclude agencies", "earlier stage only") or tighten criteria. Two refinement passes usually close the gap. See [Refine Your Pipeline](/docs/guides/refining).
## Data and enrichment
### A property is empty on most leads
Properties are filled from publicly available information. If a property comes back empty across the board, the data likely isn't public (internal metrics, unpublished emails) or the property is described too vaguely for Pioneer to know what to extract. Make the description specific: "Head of Sales LinkedIn URL" beats "contact info". And when a property is missing on just one lead you care about, hover the empty value and click the **search icon** (**Search?**) to run a targeted pass on that field alone.
### Pioneer didn't find a person's email
Contact details are found, never guessed. If the card shows no email, Pioneer looked and couldn't find one it could stand behind. You'll see the difference between "not found" and "not checked" on the card. Re-running enrichment picks up where it left off and keeps searching without overwriting anything already found.
For a single missing field there's a faster, targeted option: hover over the empty field on the person's contact card, click the small **search icon** that appears, and confirm **Search?**. Pioneer runs a research pass that chases just that field. Nothing else on the lead is touched, and it doesn't cost anything. See [Correct Pioneer's Research](/docs/guides/accuracy#missing-not-wrong).
### What do the email verification badges mean?
- **✓** verified deliverable
- **?** uncertain (the domain accepts all mail, so it can't be confirmed)
- **✗** likely to bounce
Generic inboxes (info@, sales@) are never presented as a person's email.
## Board and workflow
### I can't find the import button
Importing lives in the Leads column: click **more leads** in the column header, then **Upload your own list**. See [Import Your Own Leads](/docs/features/import).
### A whole column seems to be missing
Columns can be collapsed to save space. Look for a collapsed strip at the edge of the board and click to expand it.
### I rejected a lead by mistake
Nothing is deleted. Open the Rejected column and move the lead back. Approvals, rejections, and stage moves are all reversible.
### Can I rename columns or add my own?
Yes. Add custom stages between Relevant and Done to match your workflow ("Contacted", "Meeting Scheduled"), and rename Done to whatever fits ("Won", "Closed"). The full board tour: [Your Pipeline & Board](/docs/pipelines).
## Sharing
### My guest says the pipeline link is no longer available
Two usual causes. Either that share was revoked (open the **Share** dialog on the pipeline to see who still has access), or your guest is opening an old link from an earlier share. Revoked links never come back to life; create a fresh share and send the new link (email invites go straight to their inbox, named links land on your clipboard). See [Sharing a Pipeline](/docs/features/sharing).
### Can my guest change anything or use my credits?
No. The shared view is read-only: no editing, no moving leads, no lead generation, and nothing your guest does can spend your credits. If they need the data itself rather than the view, [export the board](/docs/features/export) and send them the file.
### Can I share a pipeline without sending an email?
Yes. In the **Share** dialog, type a name for the link instead of an email address ("Alex", "Board deck") and click **Create link**. Pioneer copies a personal link to your clipboard and you deliver it however you like: text, DM, or a slide. It behaves exactly like an emailed share, read-only and revocable on its own. Details: [Sharing a Pipeline](/docs/features/sharing).
## Account
### I just signed up and there's already a pipeline in my account
That's intentional. The Pioneer team sometimes builds a pipeline for a company before anyone there signs up, with real leads, researched and qualified. When you create your account with your work email, it's automatically handed to your workspace. It's fully yours to edit, refine, or archive. See [Your first pipeline might already exist](/docs/first-pipeline#your-first-pipeline-might-already-exist).
### What happens when I run out of credits?
Lead generation pauses; nothing is lost. Your pipelines, board, and existing leads stay fully accessible, and enrichment on existing leads keeps working. See [Credits & Billing](/docs/credits).
### Something else is wrong
Email [support@pioneerclimate.com](mailto:support@pioneerclimate.com), and include the pipeline name and, if it's about a specific lead, the lead's name. A human reads every message.
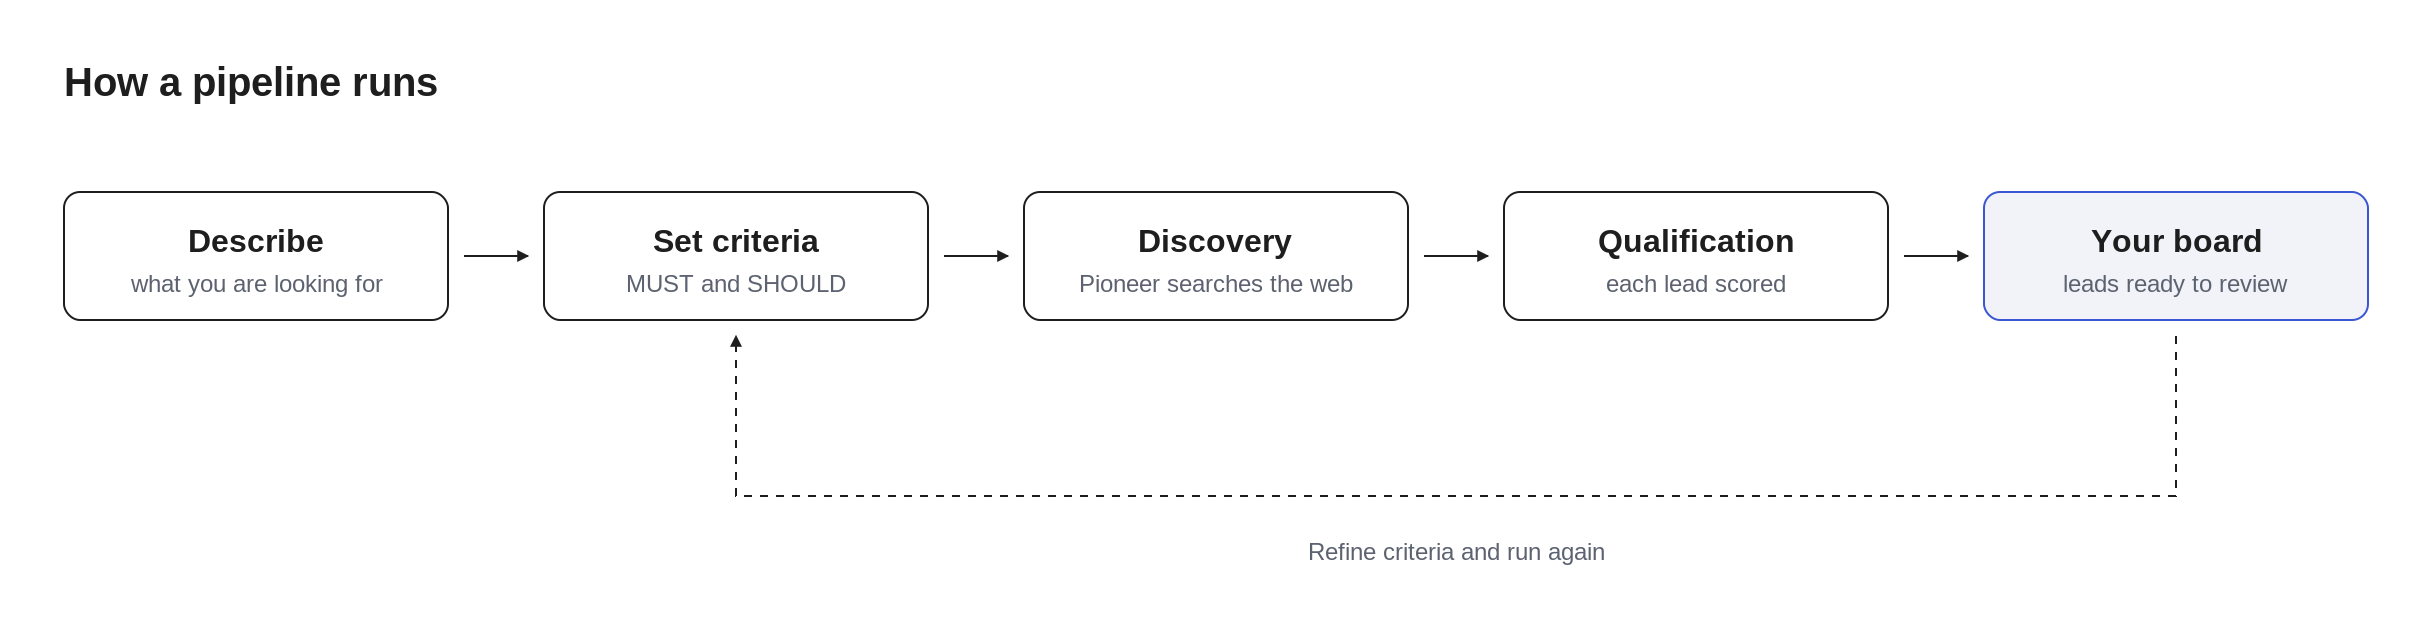 ## Let your agent do the setup with you
Pioneer is built to work with the AI agent you already use (Claude, ChatGPT, Codex, or any other). During signup you'll get a short setup message you can paste straight into your agent, and your agent will guide itself through connecting to Pioneer; it can even create this first pipeline for you. The same message is one click away later, via the **ask your agent to do it** prompt on the `/pipelines` page.
The message points at [Use Pioneer With Your Agent](/docs/agents), the full agent setup guide. Credentials are minted only when you ask, and shown exactly once.
Prefer to set everything up yourself? Everything on this page works by hand too; the agent path is a shortcut, not a requirement.
## Your first pipeline might already exist
Some teams sign up and find a pipeline already sitting in their account, built by the Pioneer team, with real leads researched and qualified for their business. If that's you, here's what to know:
**What it is.** We sometimes build a pipeline for a company we think Pioneer can help, before anyone there has an account. When someone signs up with a work email from that company, the pipeline is automatically handed to their workspace.
**It's yours now.** Everything in it (the description, criteria, properties, and every researched lead) is fully editable, exactly as if you'd built it yourself. Nothing in it is demo data: the leads are real, researched against criteria we guessed for your business.
**Our guess, your call.** We wrote the description and criteria from public information about your company. Treat them as a first draft: skim the leads, then adjust the criteria in the **Preferences** column so they match how *you* actually qualify. Refining is the whole point. See [Refine Your Pipeline](/docs/guides/refining).
**Start by reviewing, not creating.** The fastest way to get value is to open the pipeline, approve a few leads that look right, reject a few that don't, and steer from there. You can always create more pipelines alongside it. The rest of this page walks through building one from scratch.
## Start from a recipe or from scratch
From the `/pipelines` page, you have two options:
**From a recipe:** Click **Try this** on any suggested recipe. Recipes are pipeline ideas Pioneer generates from your stated purpose, deliberately specific and narrow, because "Series A battery-recycling startups in the EU" makes a far better pipeline than "companies in energy". A recipe pre-fills everything; you can still customize before creating.
**From scratch:** Expand the "Create a custom pipeline" section and describe what you're looking for.
Either way, the two decisions that matter are the next two steps: the description and the criteria. Everything Pioneer finds flows from them.
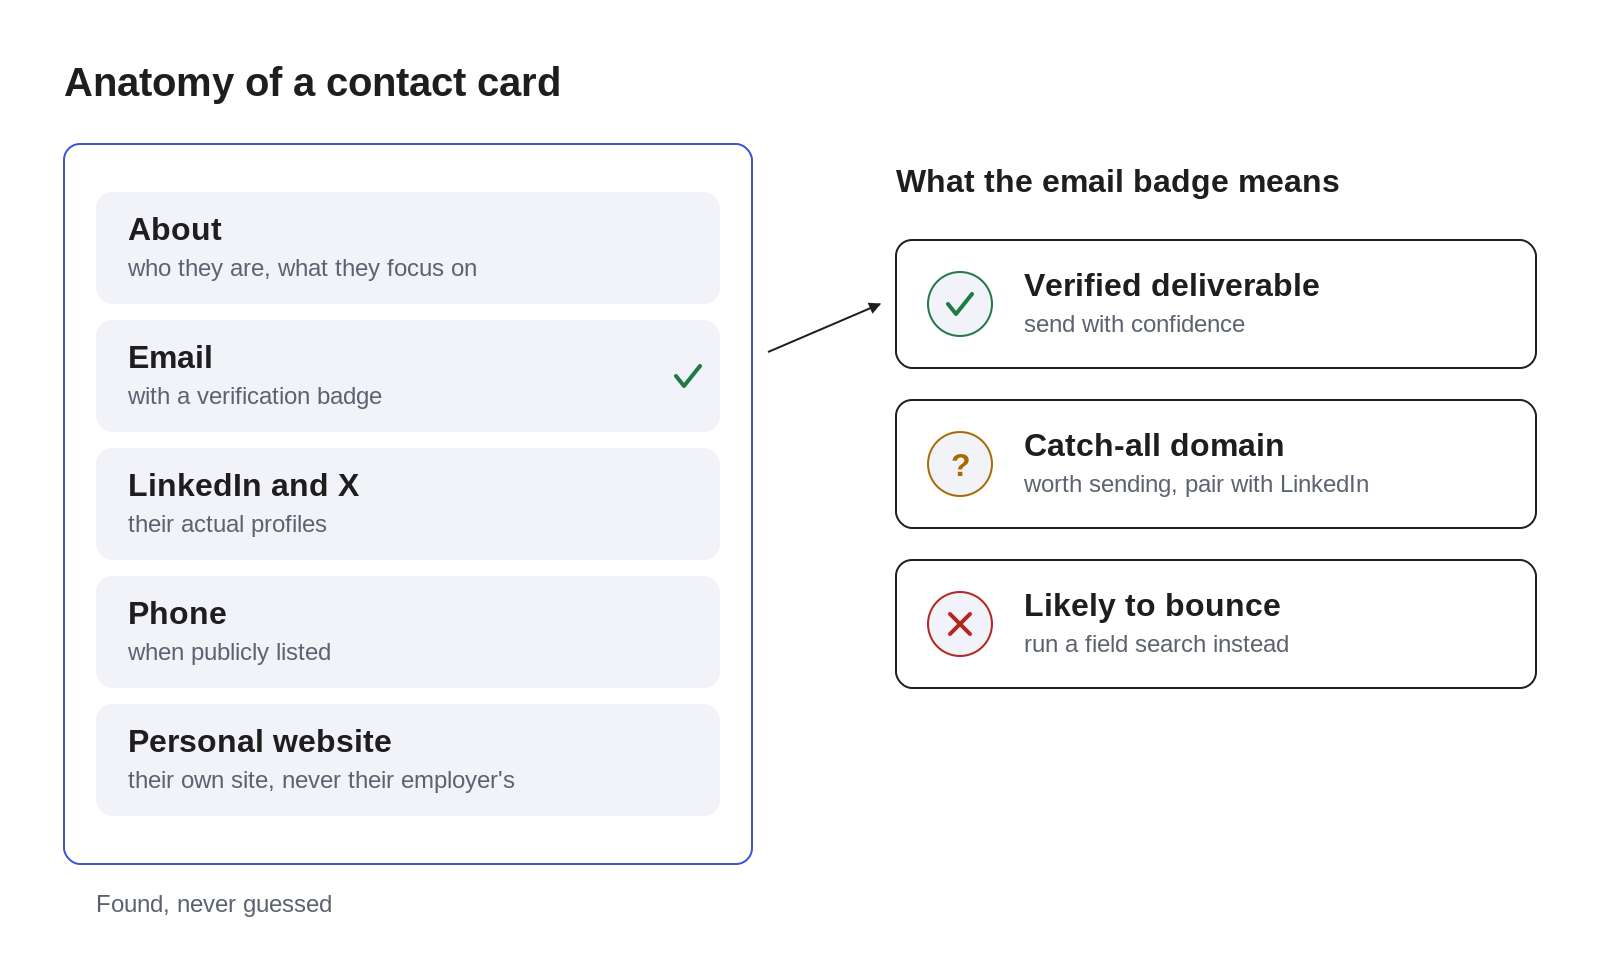 ### Grounded, never guessed
Contact details only appear when Pioneer actually found them on a real page. Emails are never pattern-guessed, and generic inboxes (info@, sales@) are never presented as a person's email. Every detail is tied to the specific person by name, so a colleague's email at the same company won't be attributed to them. Why so strict: one confidently-wrong email costs you a bounce, a burned first impression, and your trust in everything else on the card. An honest blank is the better deal.
### It keeps digging
If a person is missing details (no email yet, no LinkedIn), re-running enrichment picks up where it left off and keeps searching, filling gaps without overwriting anything already found. For one specific missing detail, you don't need a full re-run: hover the empty field on the contact card and click the **search icon** that appears (**Search?**), and Pioneer chases just that field. The same control appears on empty property values. See [Correct Pioneer's Research](/docs/guides/accuracy#missing-not-wrong).
The full person workflow (choosing your champion, reading the card, turning it into outreach) has its own guide: [Find the Right People](/docs/guides/people).
## Chain properties that build on each other
Some properties depend on others: "CEO LinkedIn" needs to know who the CEO is first; "Local Regulations" needs the headquarters city. Pioneer handles this through **property dependencies**:
1. In the property editor, look for the **Depends on** option
2. Select which property this one depends on
3. Save
Pioneer enriches parent properties first, uses their values as context for the children, and figures out the right order automatically.
**Example chain:**
```
Company Name (no dependency)
↓
Company LinkedIn URL (depends on Company Name)
↓
CEO Name (depends on Company LinkedIn URL)
↓
CEO Email (depends on CEO Name)
```
Properties at the same level run in parallel, so you don't need to think about scheduling, just about what depends on what.
(For reaching people specifically, skip the chain: a single **Person** property does the identify-and-research work in one step, with verification built in.)
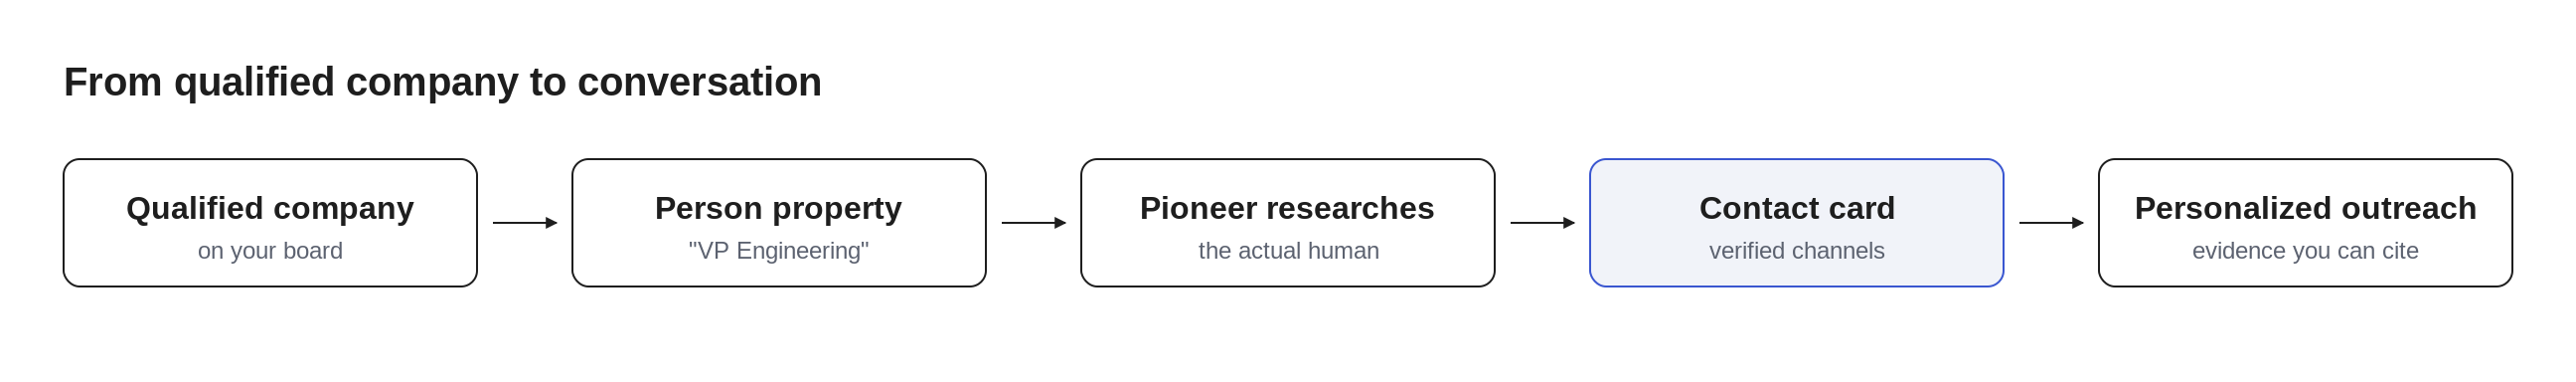 ## When the lead itself is a person
Not every pipeline chases companies. If your target is a person (a consultant to hire, a podcast guest, an investor, a speaker), add them the same way you'd add a company (by name, email, or profile link), and Pioneer researches the person themselves. The lead's card becomes their own mini-dossier: a short about, recent activity, and an email with the same verification badge described in Step 3: never a guessed address, never a generic inbox. The research-quality rules don't change just because the lead has one employee.
## Step 1: Decide who your champion is
Before adding properties, get specific about the role that says yes to you:
- Selling a developer tool? Your champion is probably a **VP of Engineering** or **CTO**, not the CEO.
- Selling to finance teams? **Controller** or **VP Finance**.
- Early-stage targets? At small companies, go straight for a **founder**.
One well-chosen role beats three vague ones. You can always add a second Person property later (say, an executive sponsor alongside your hands-on champion).
## Step 2: Add a Person property
1. On your pipeline board, open the **Preferences** column and click the pencil to edit
2. Add a property and set its type to **Person**
3. Name it for the role: "CEO", "Head of Partnerships", "VP Engineering"
That's the whole setup. As leads are enriched, Pioneer identifies the actual person in that role at each company and researches them. Each found person appears on the lead as a clickable chip with their name and photo.
**Tip:** name roles the way the market names them. "Head of Partnerships" finds people; "the person who handles partnerships" makes Pioneer guess what you mean.